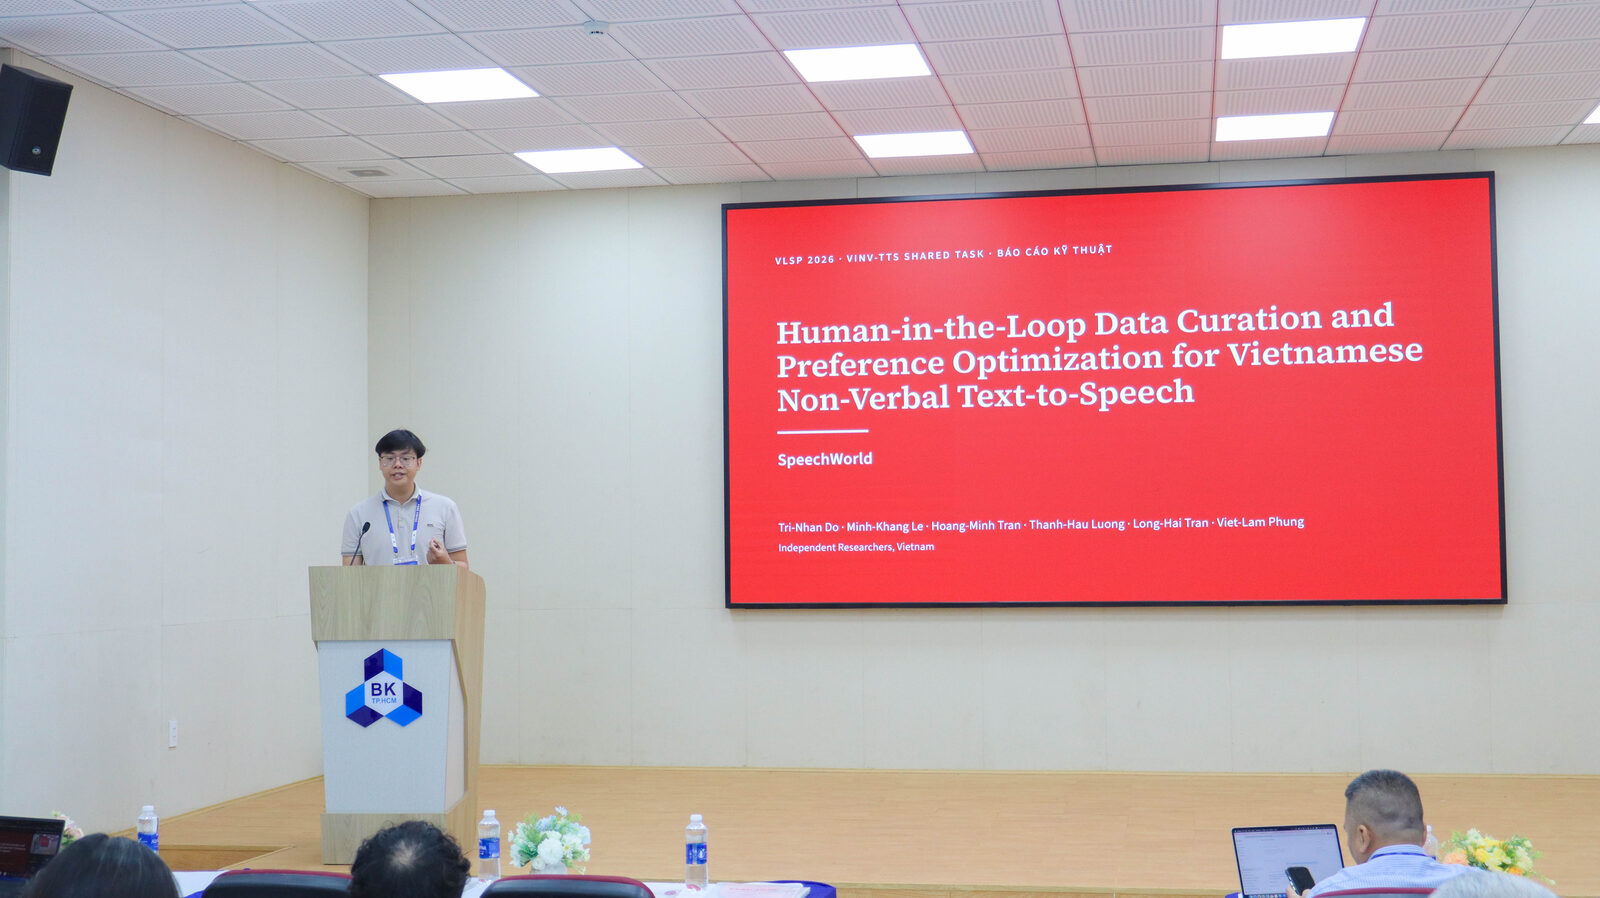
Human-in-the-Loop Data Curation and Preference Optimization for Vietnamese Non-Verbal Text-to-Speech
Presented in VLSP 2026, 2026
Authors: Tri-Nhan Do, Minh-Khang Le, Hoang-Minh Tran, Thanh-Hau Luong, Long-Hai Tran, Viet-Lam Phung
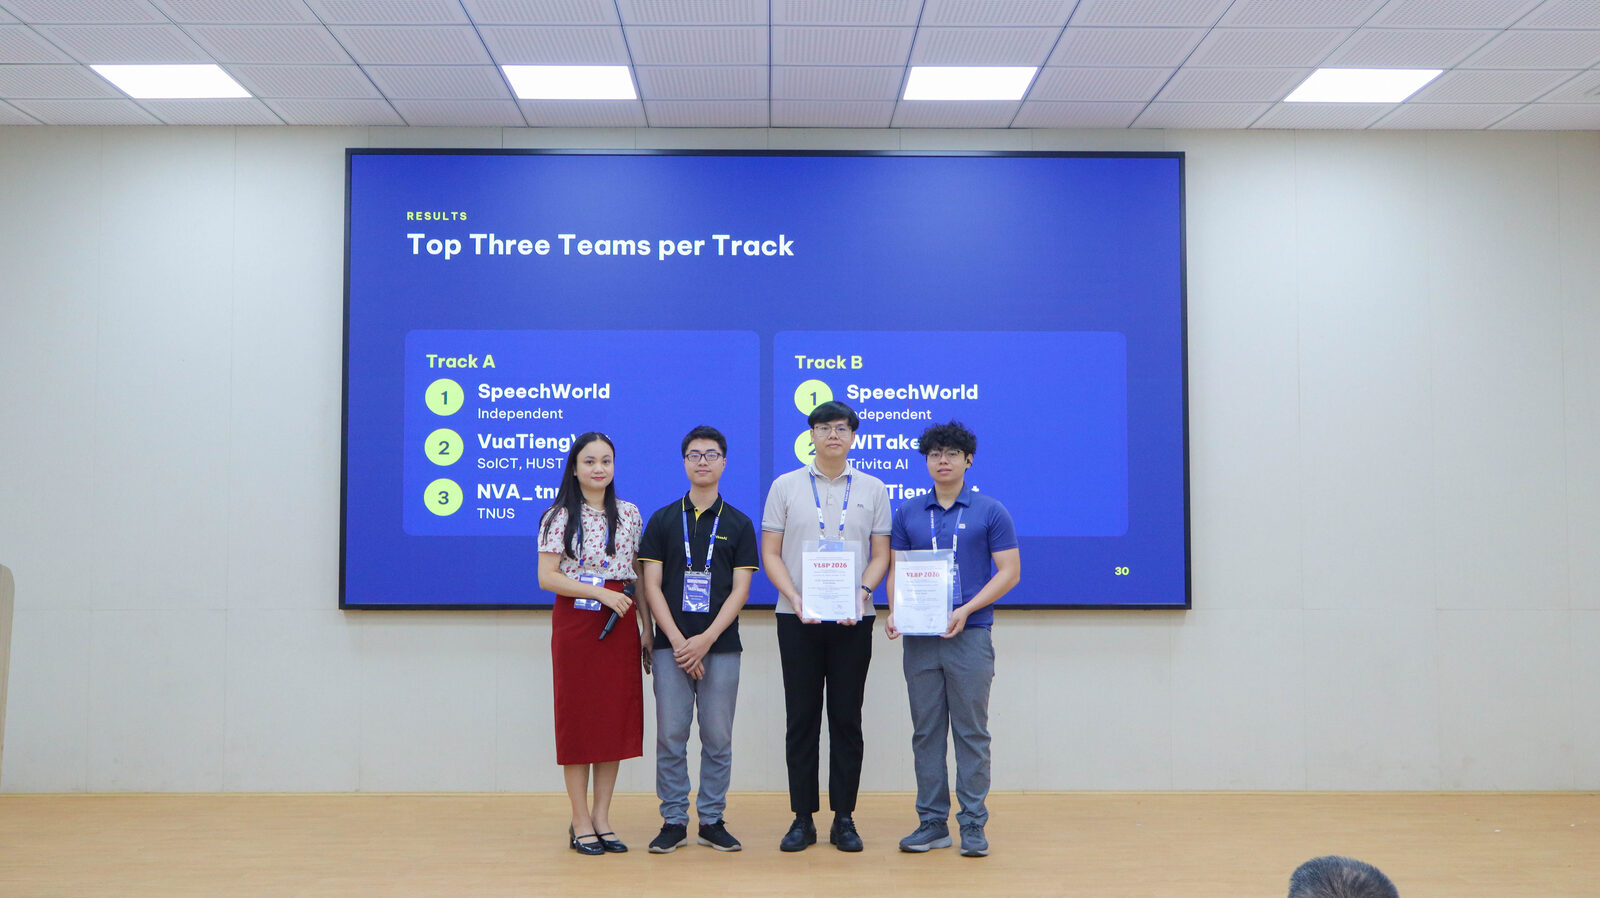
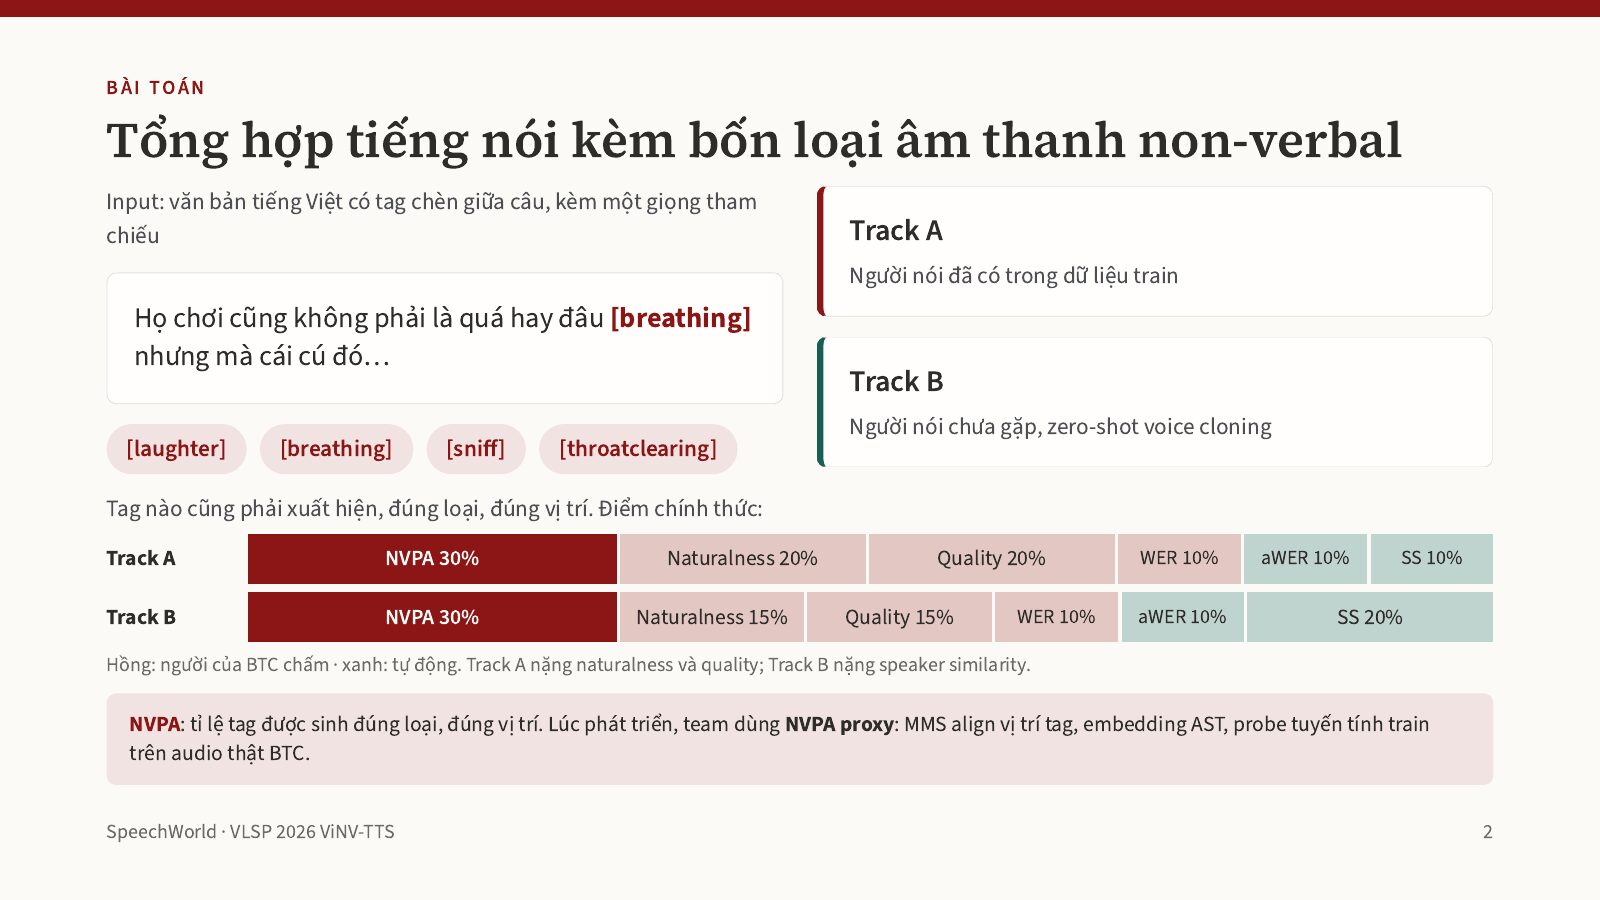
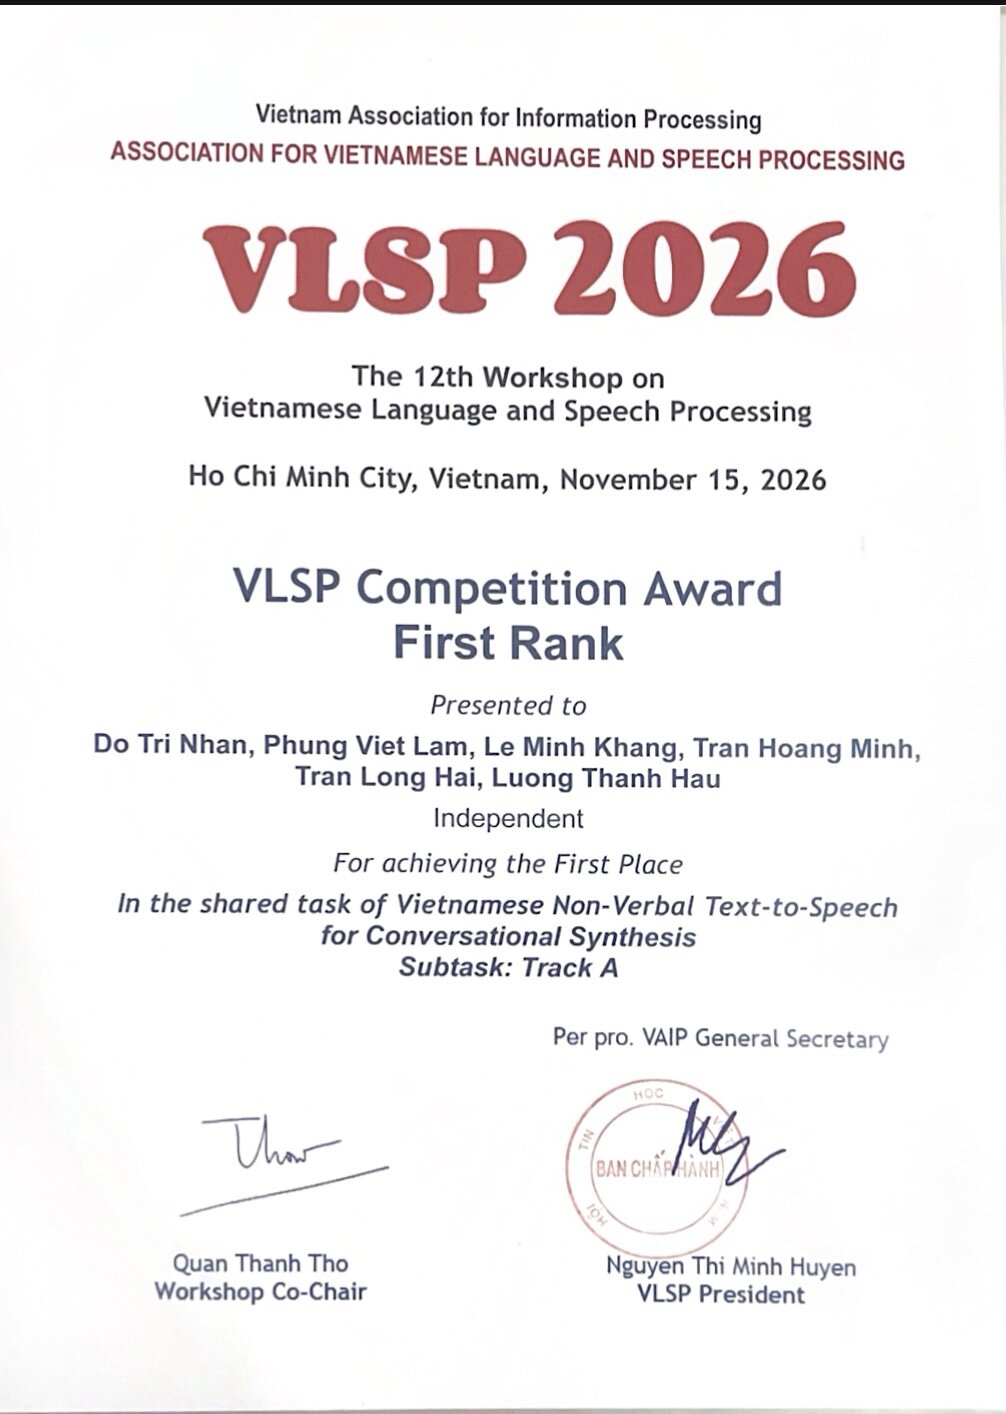
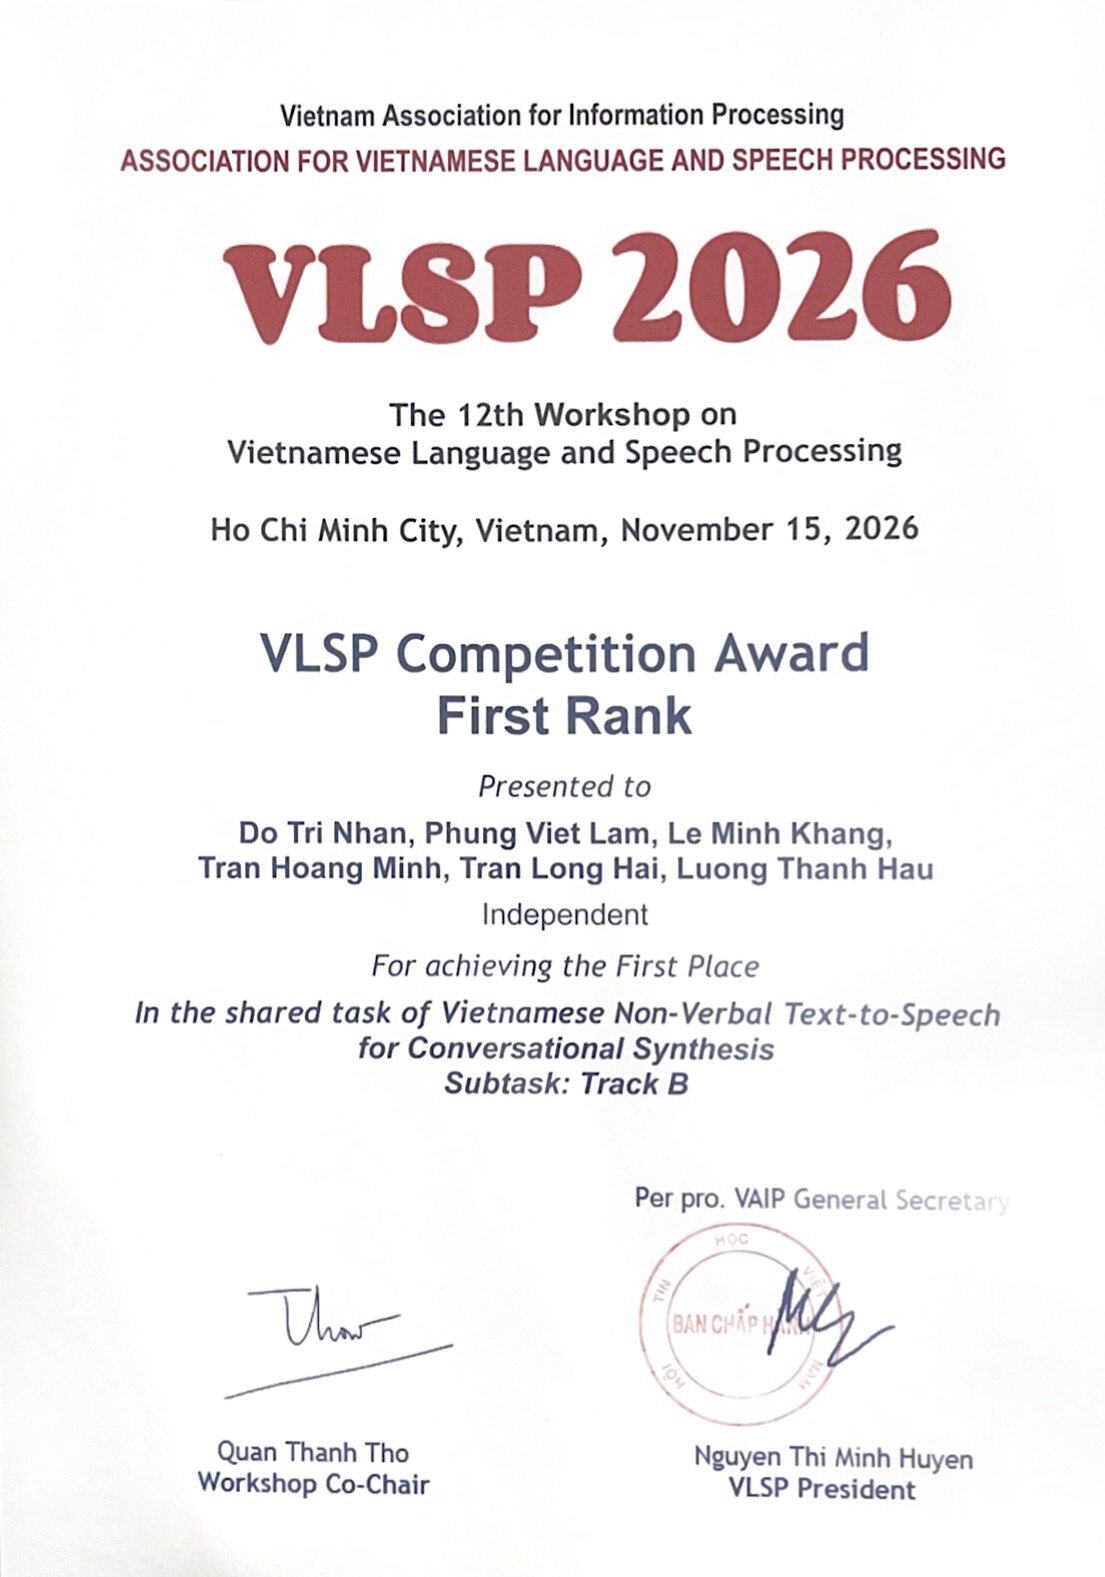
🏆 First Place in both Track A (seen speakers) and Track B (zero-shot voice cloning) of the VLSP 2026 shared task on Vietnamese Non-Verbal Text-to-Speech for Conversational Synthesis (Team SpeechWorld).
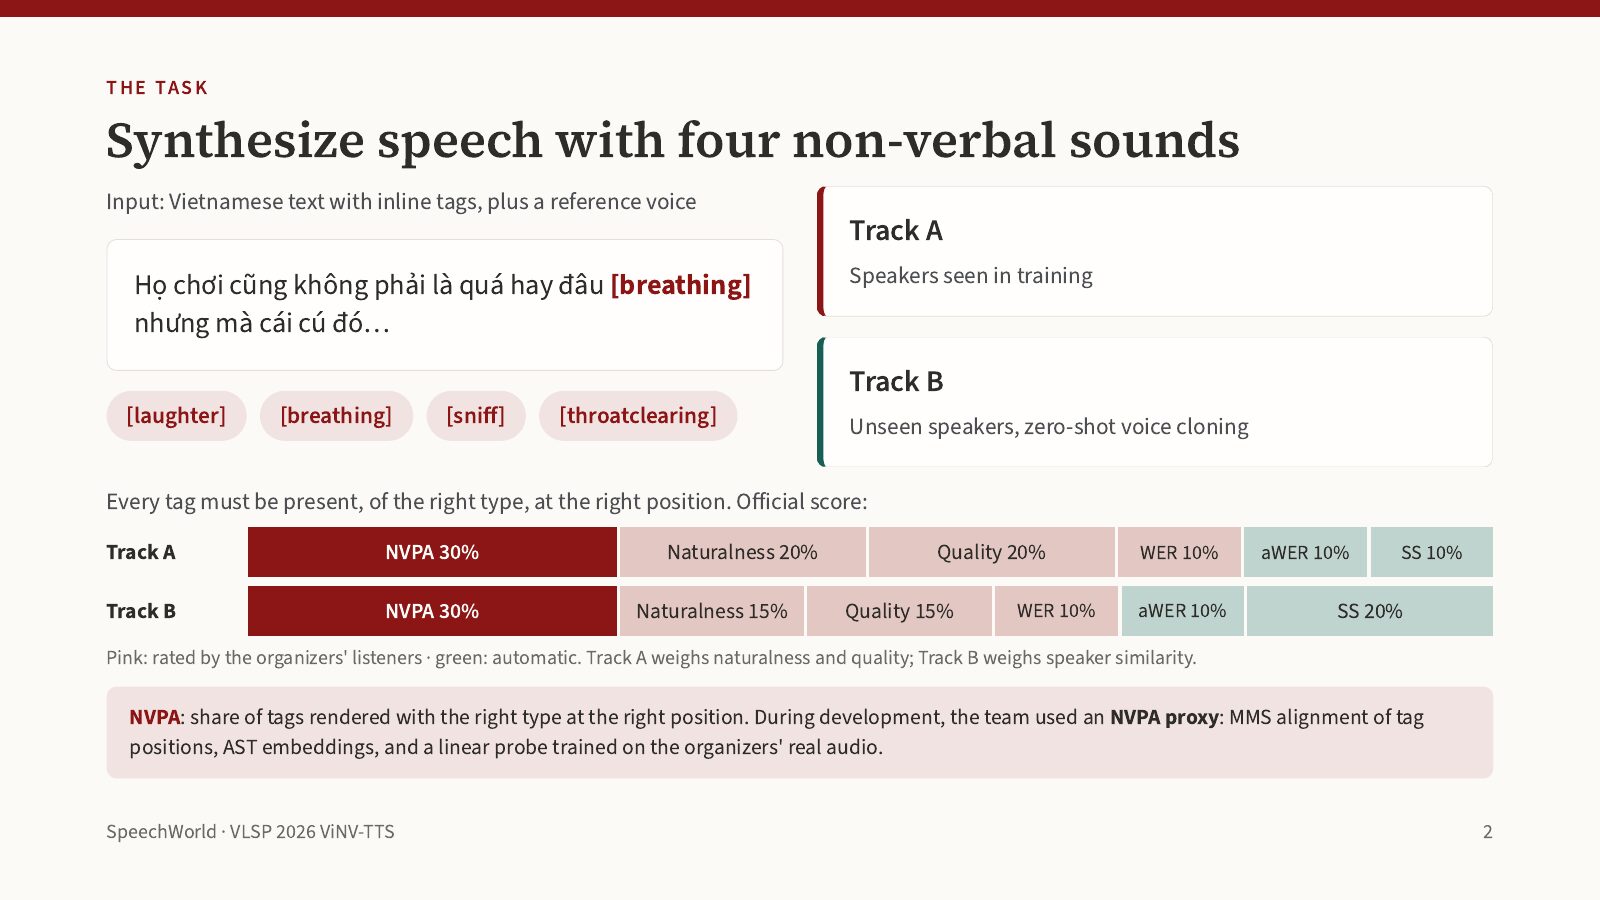
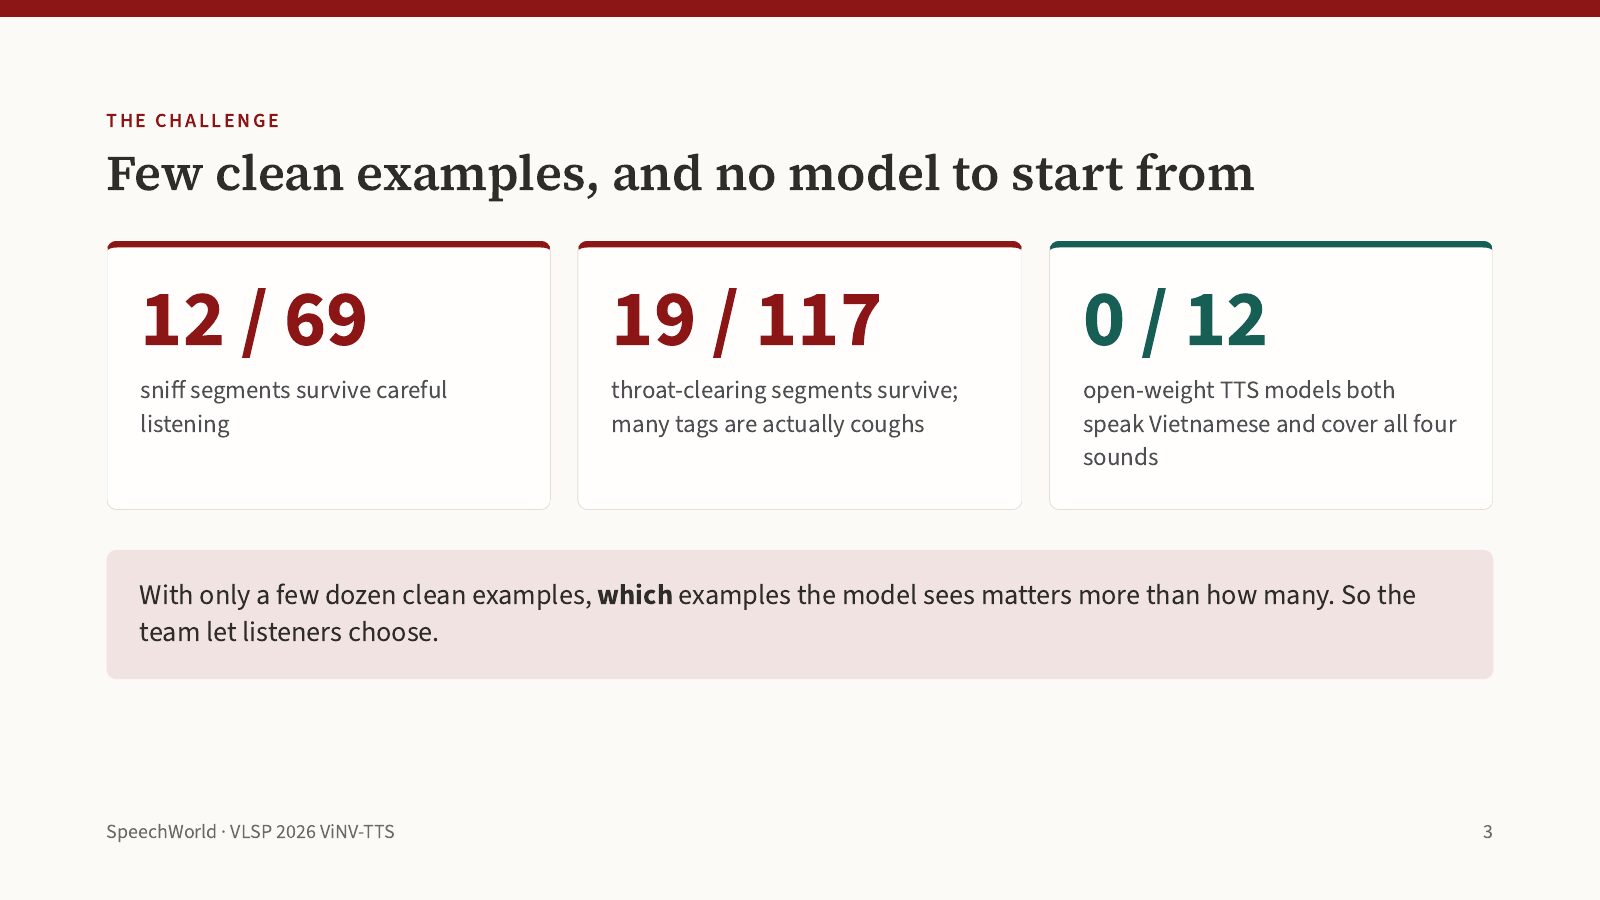
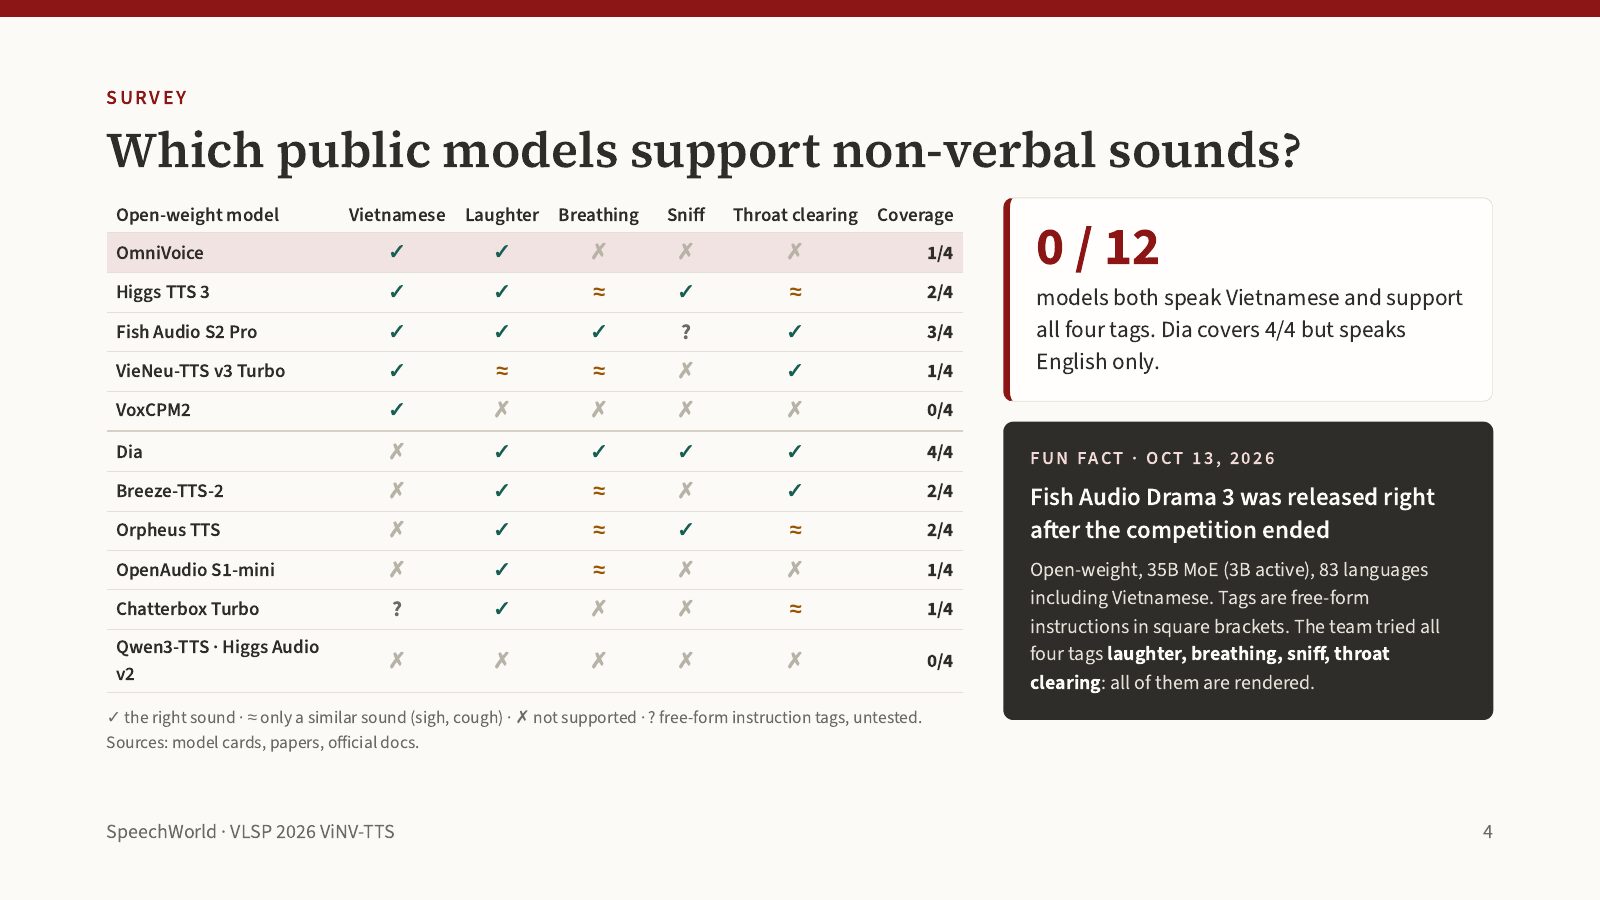
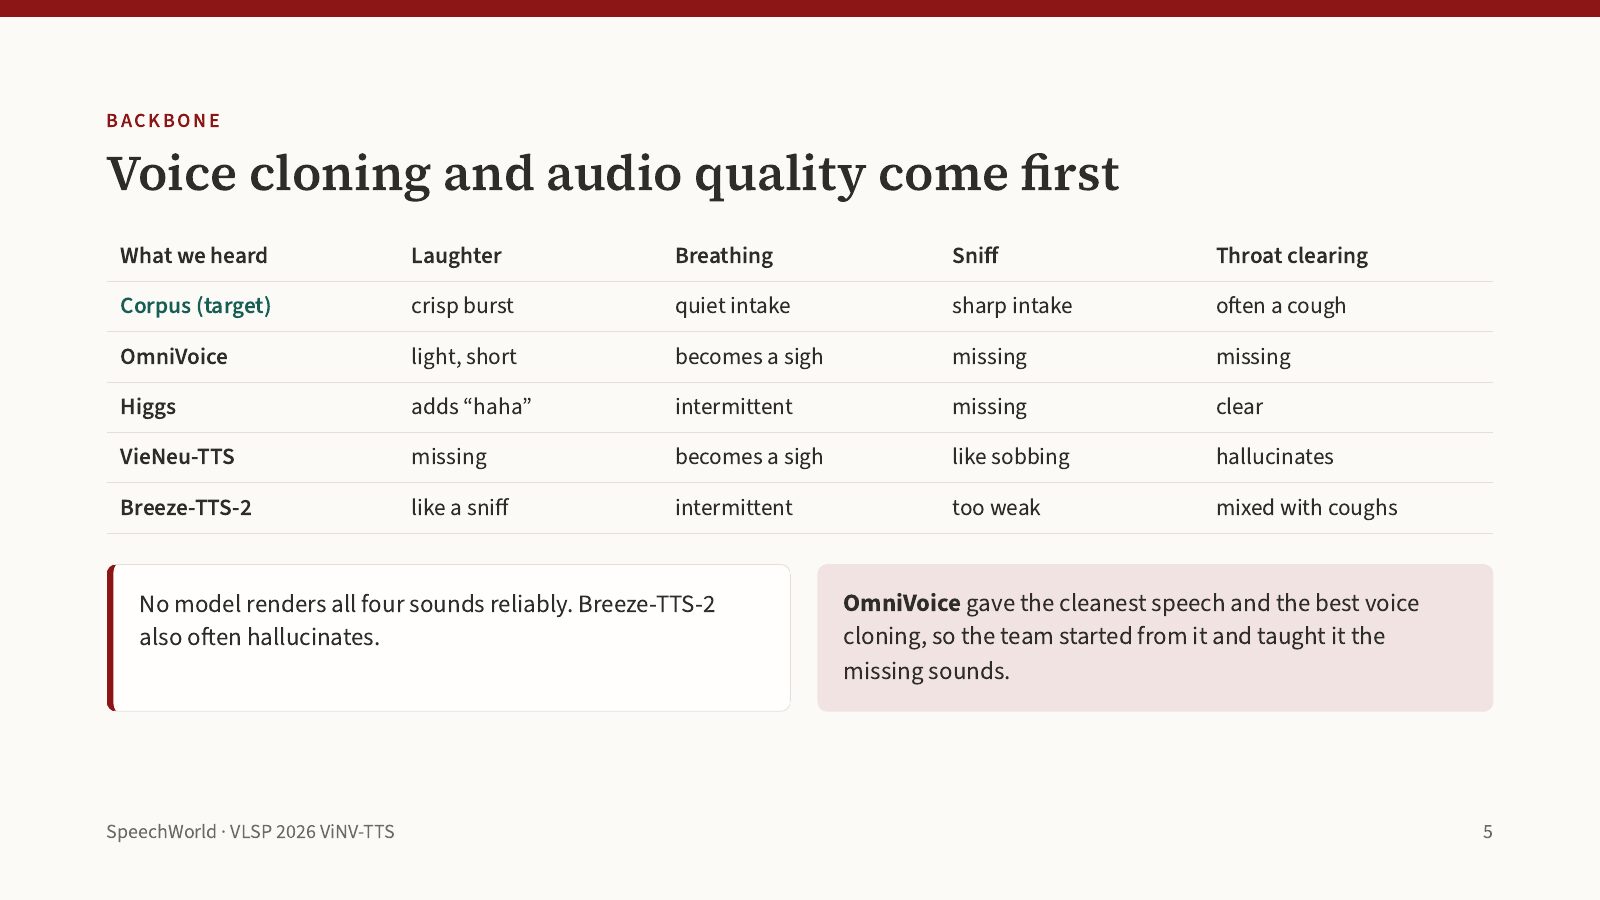
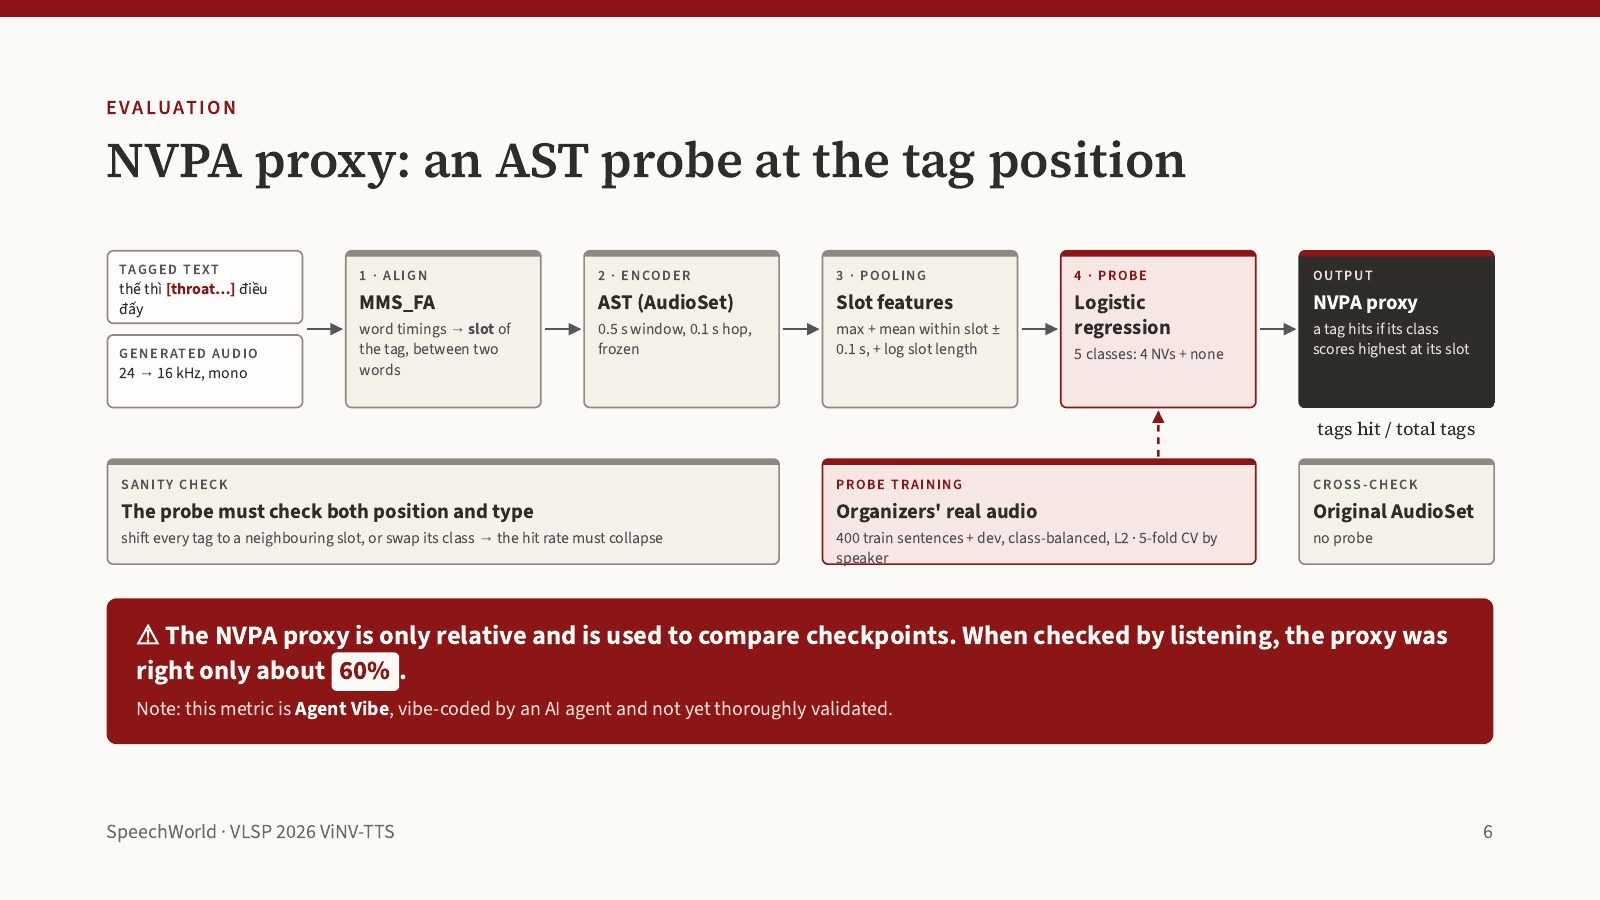
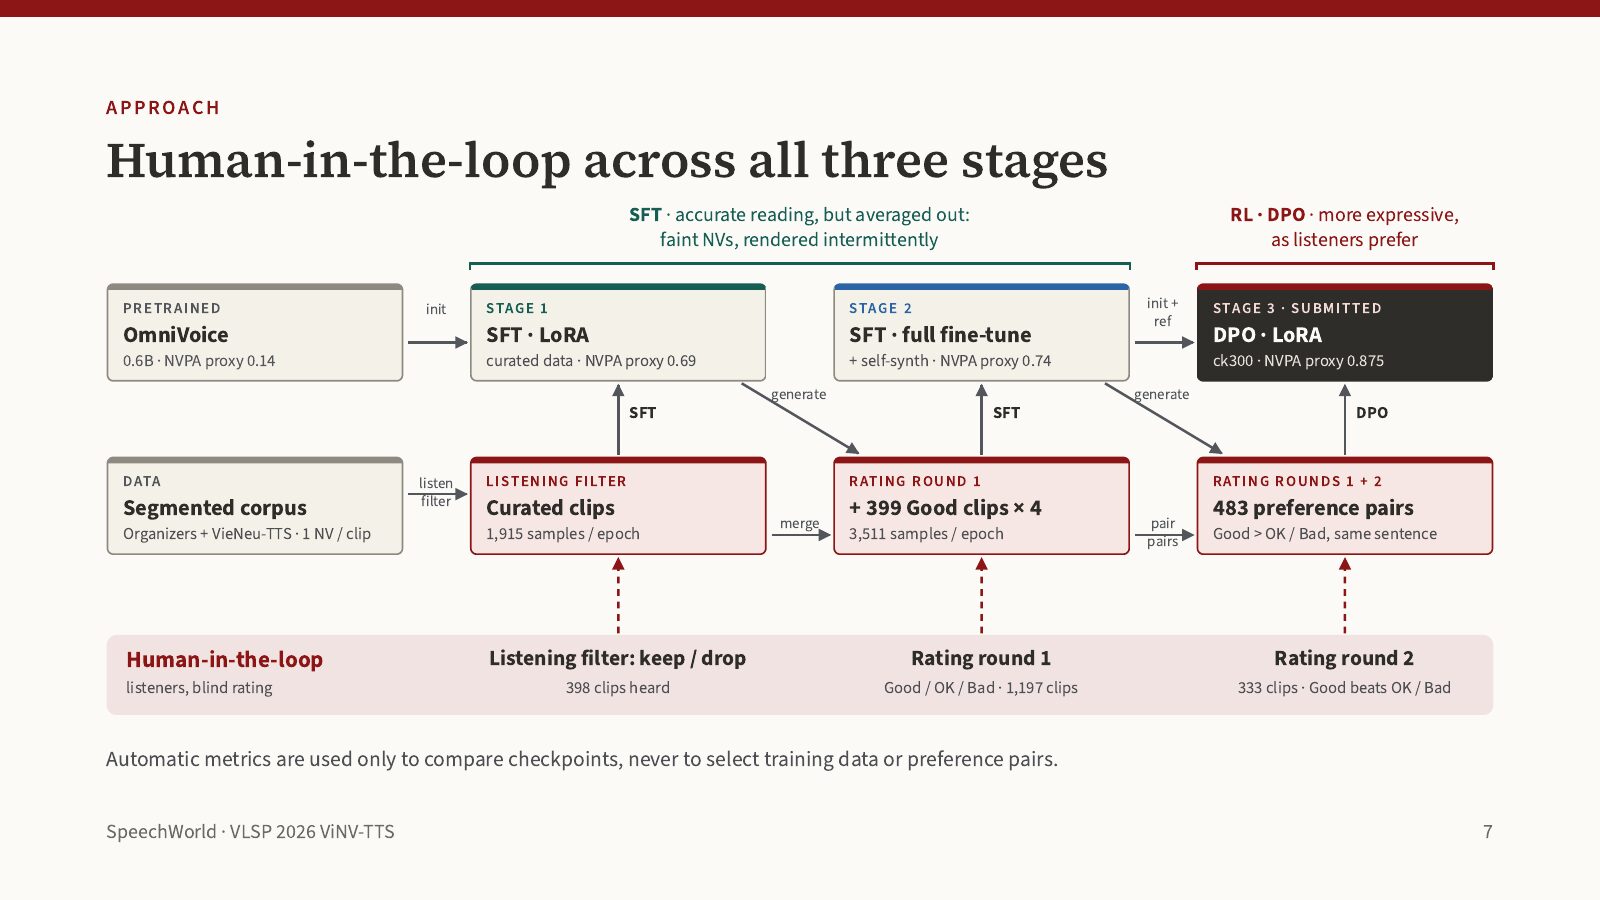
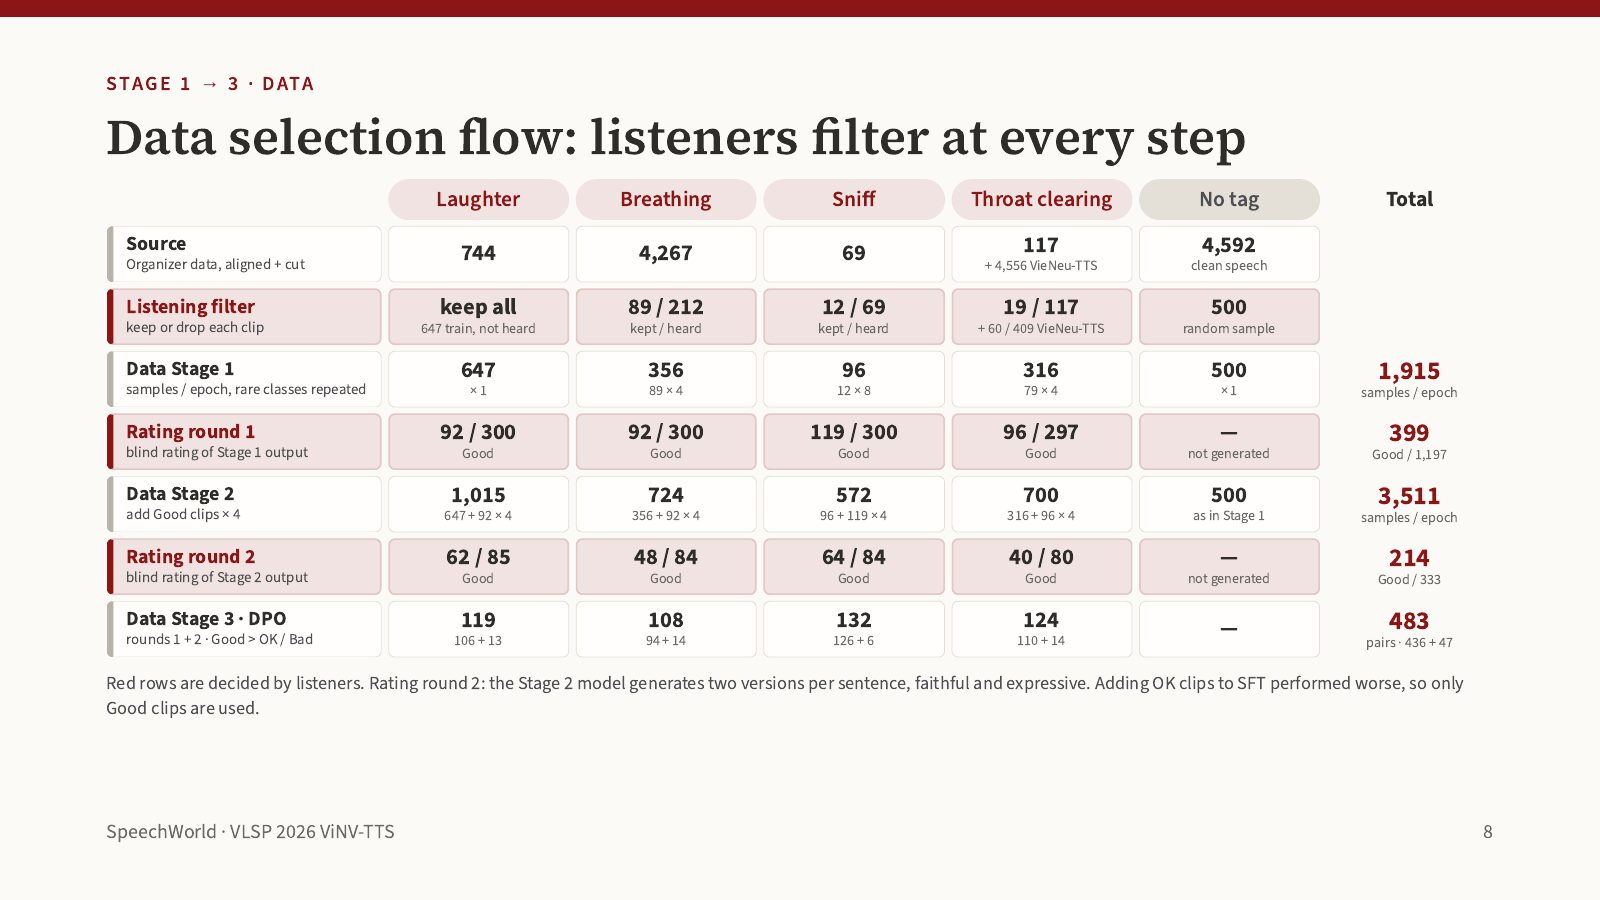
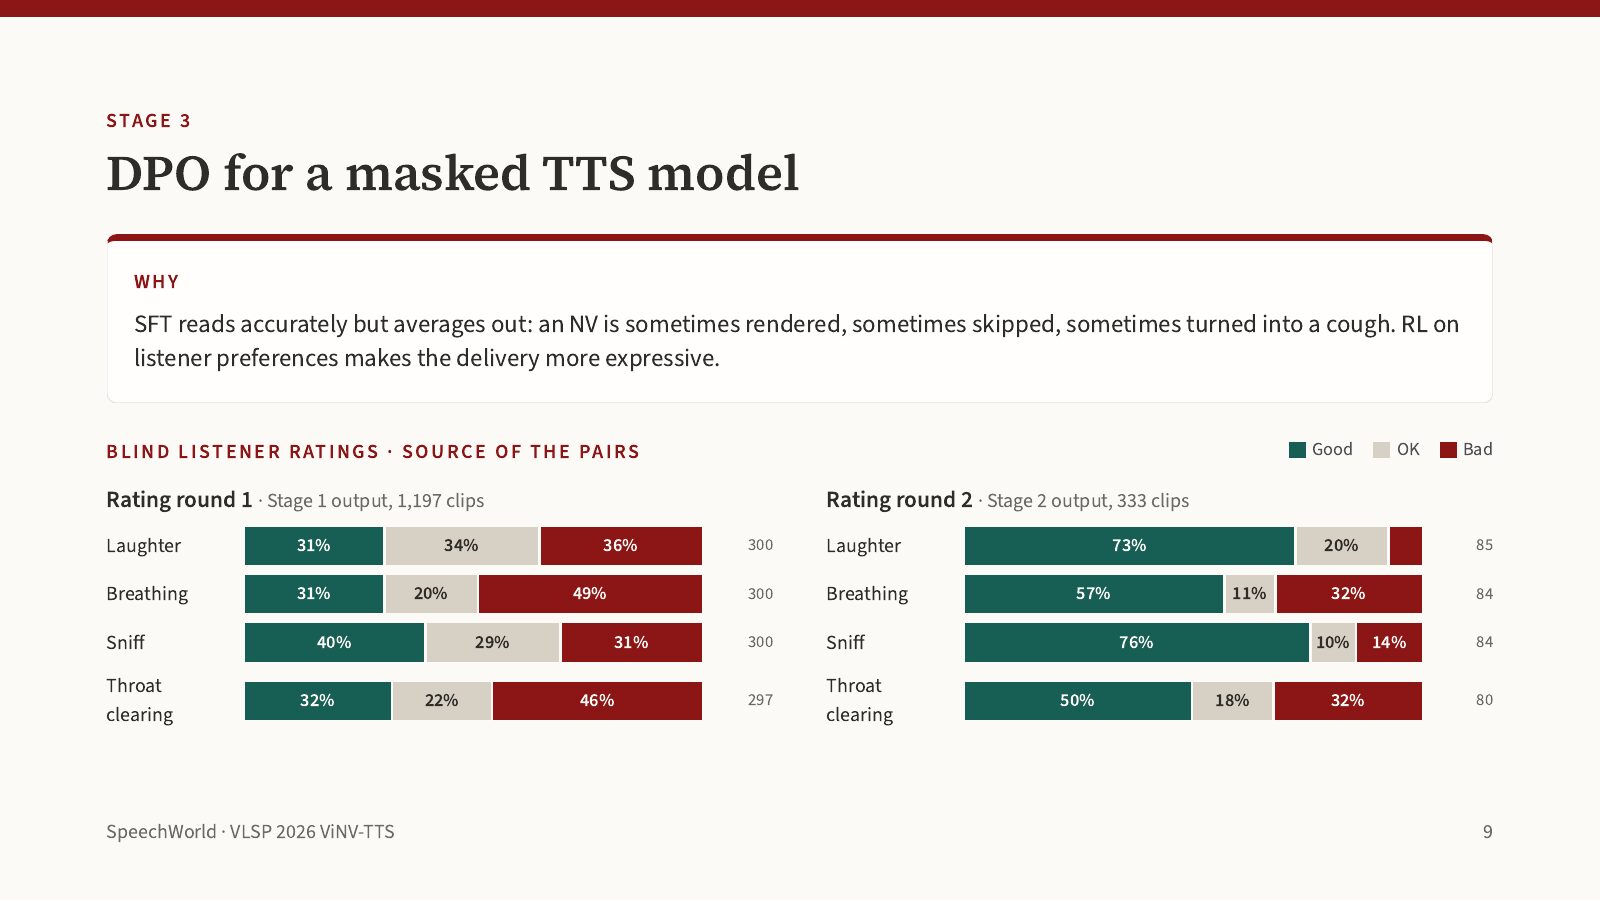
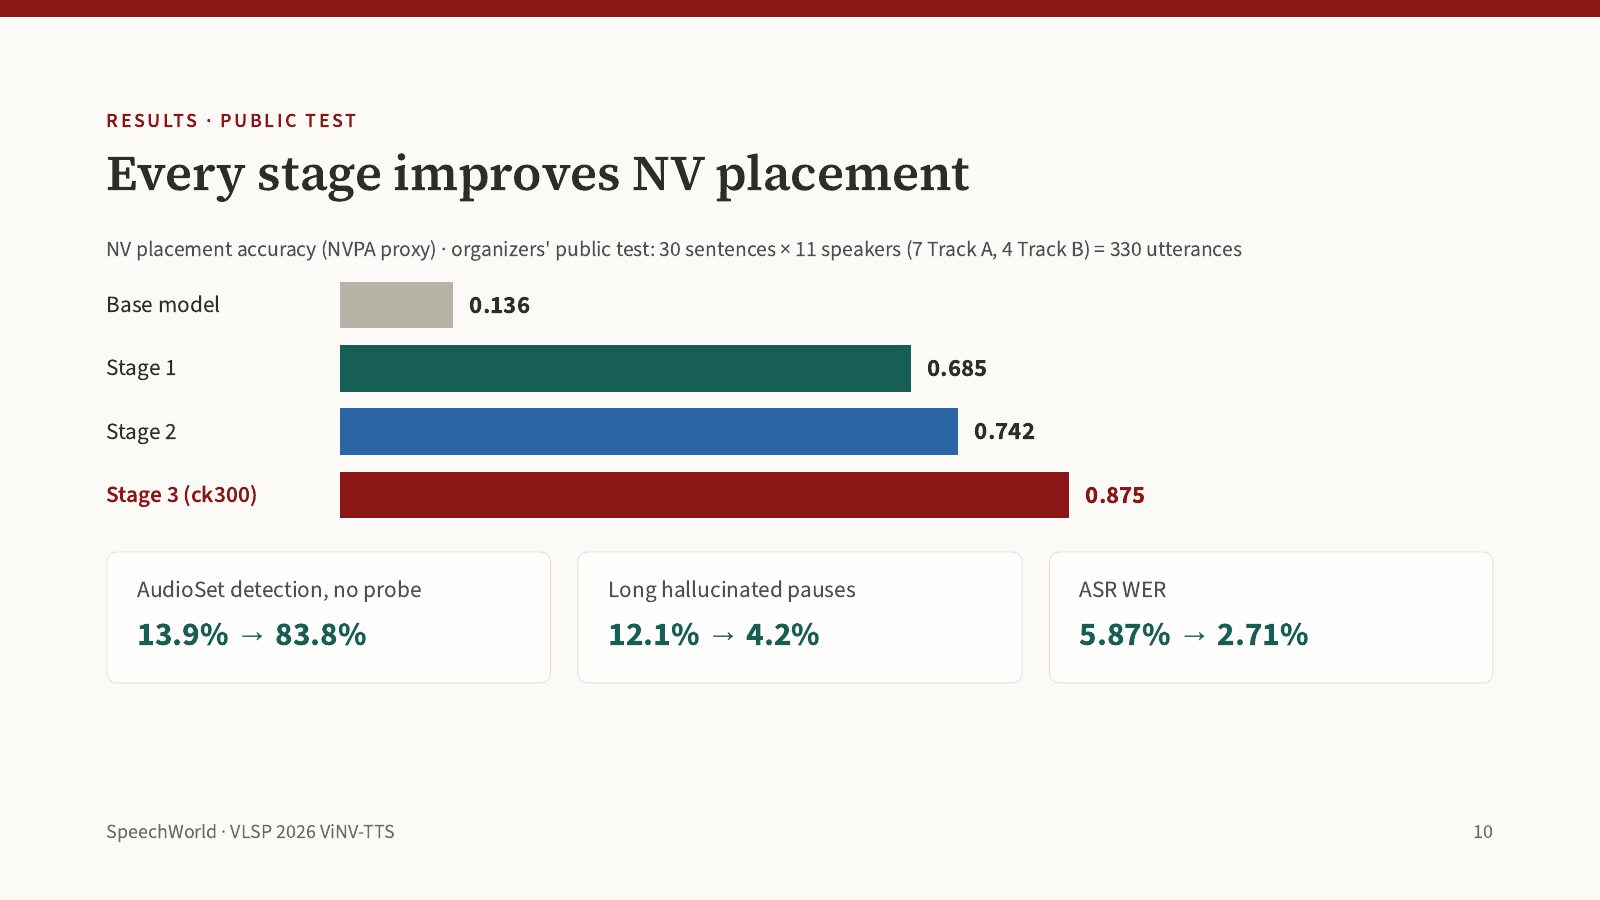
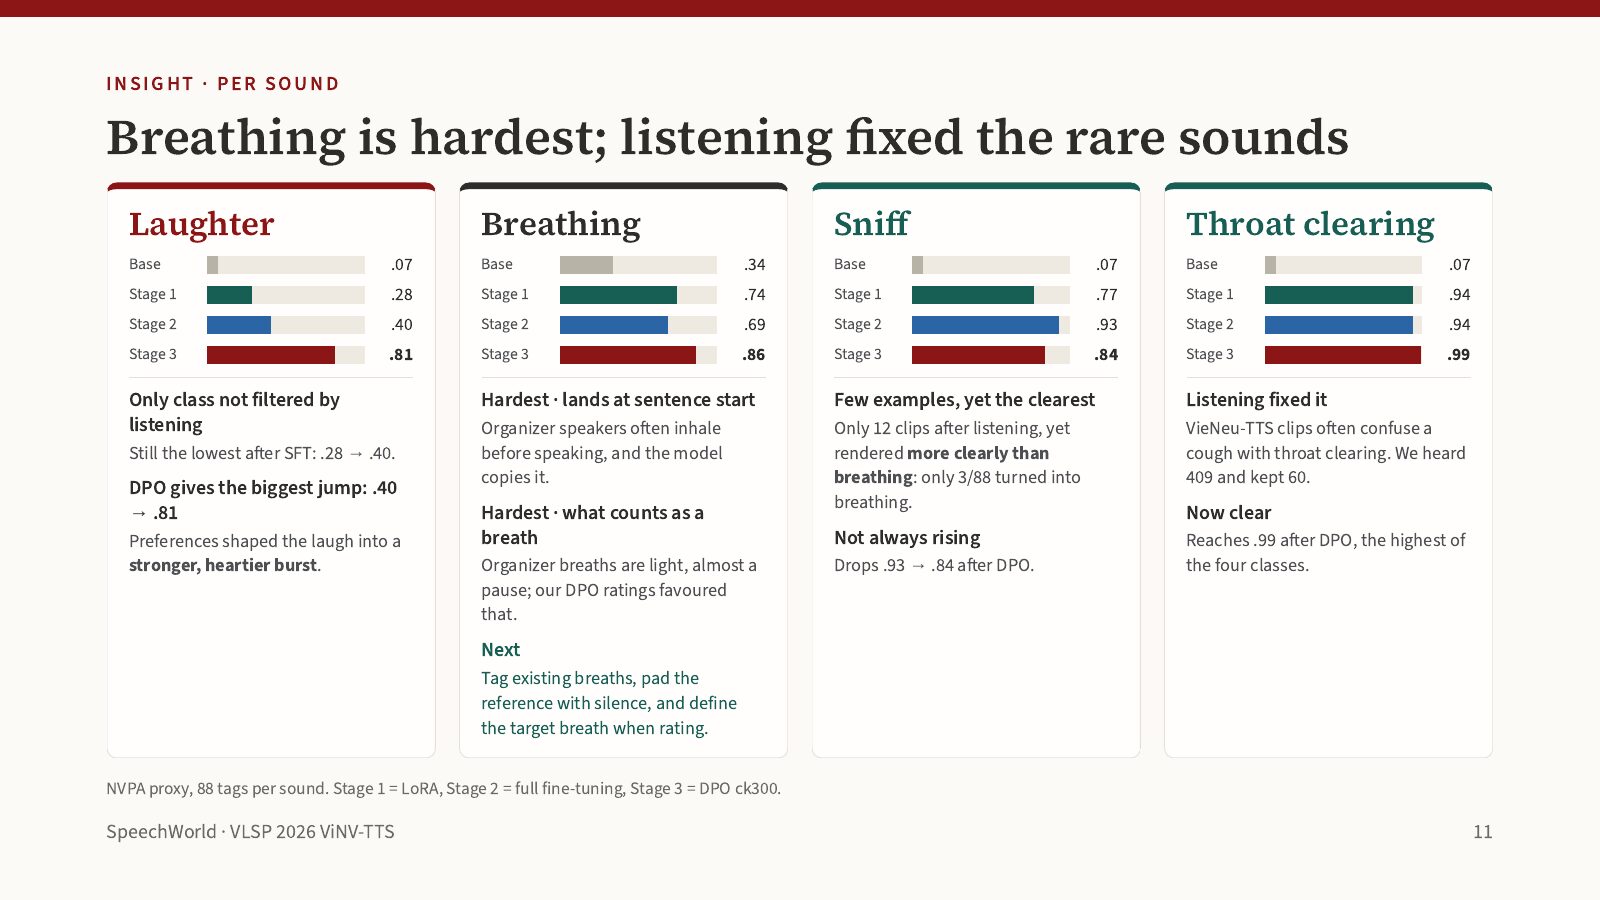
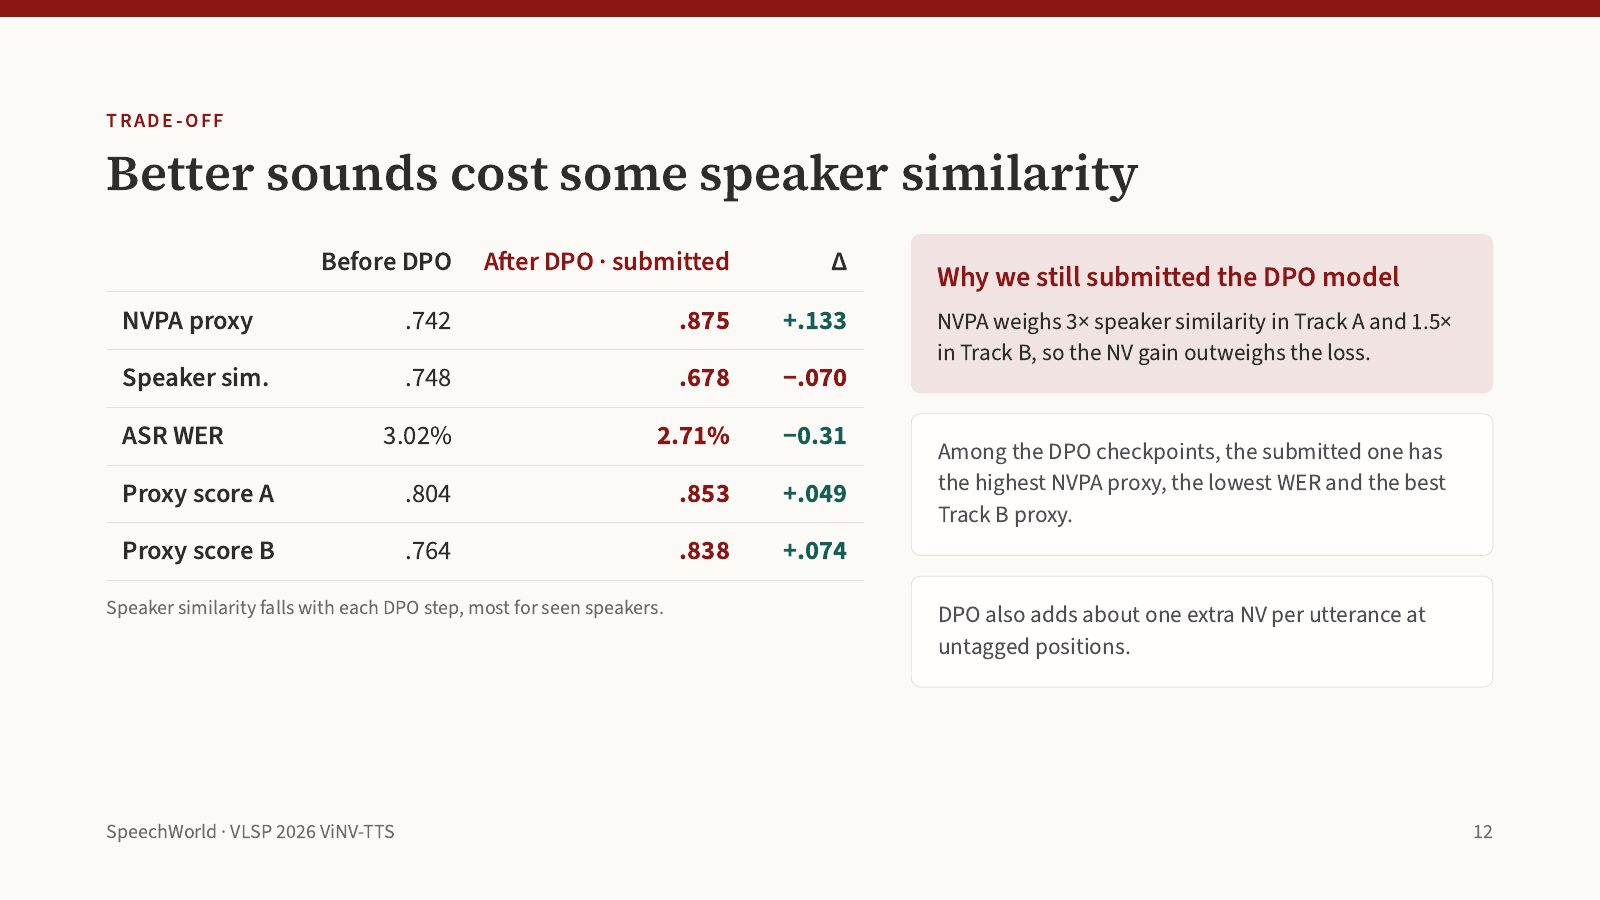
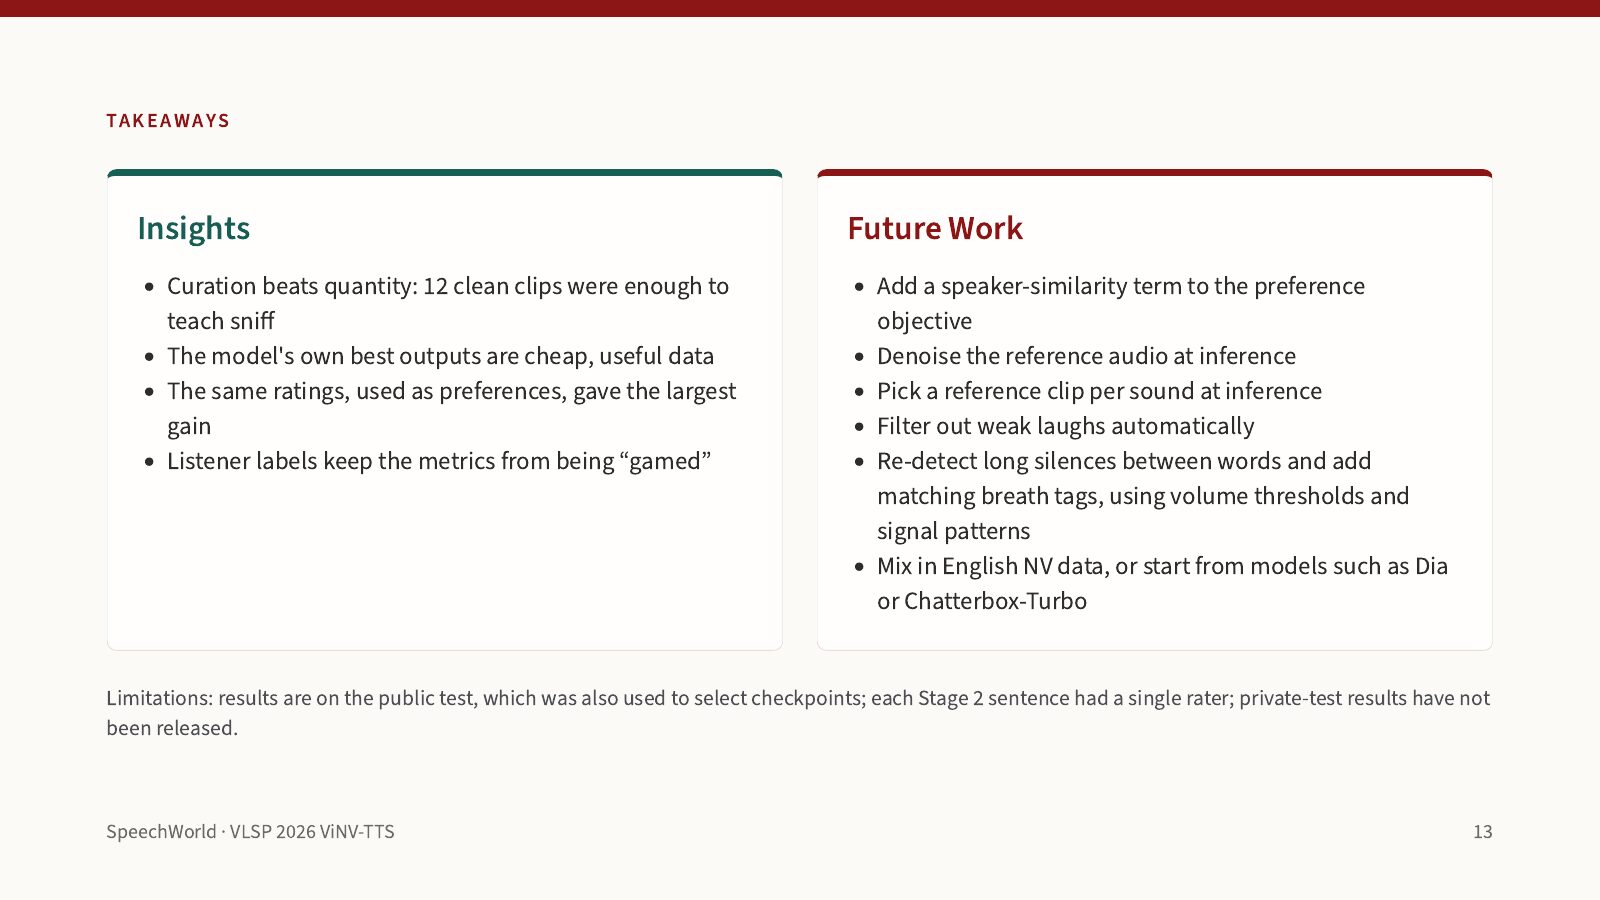
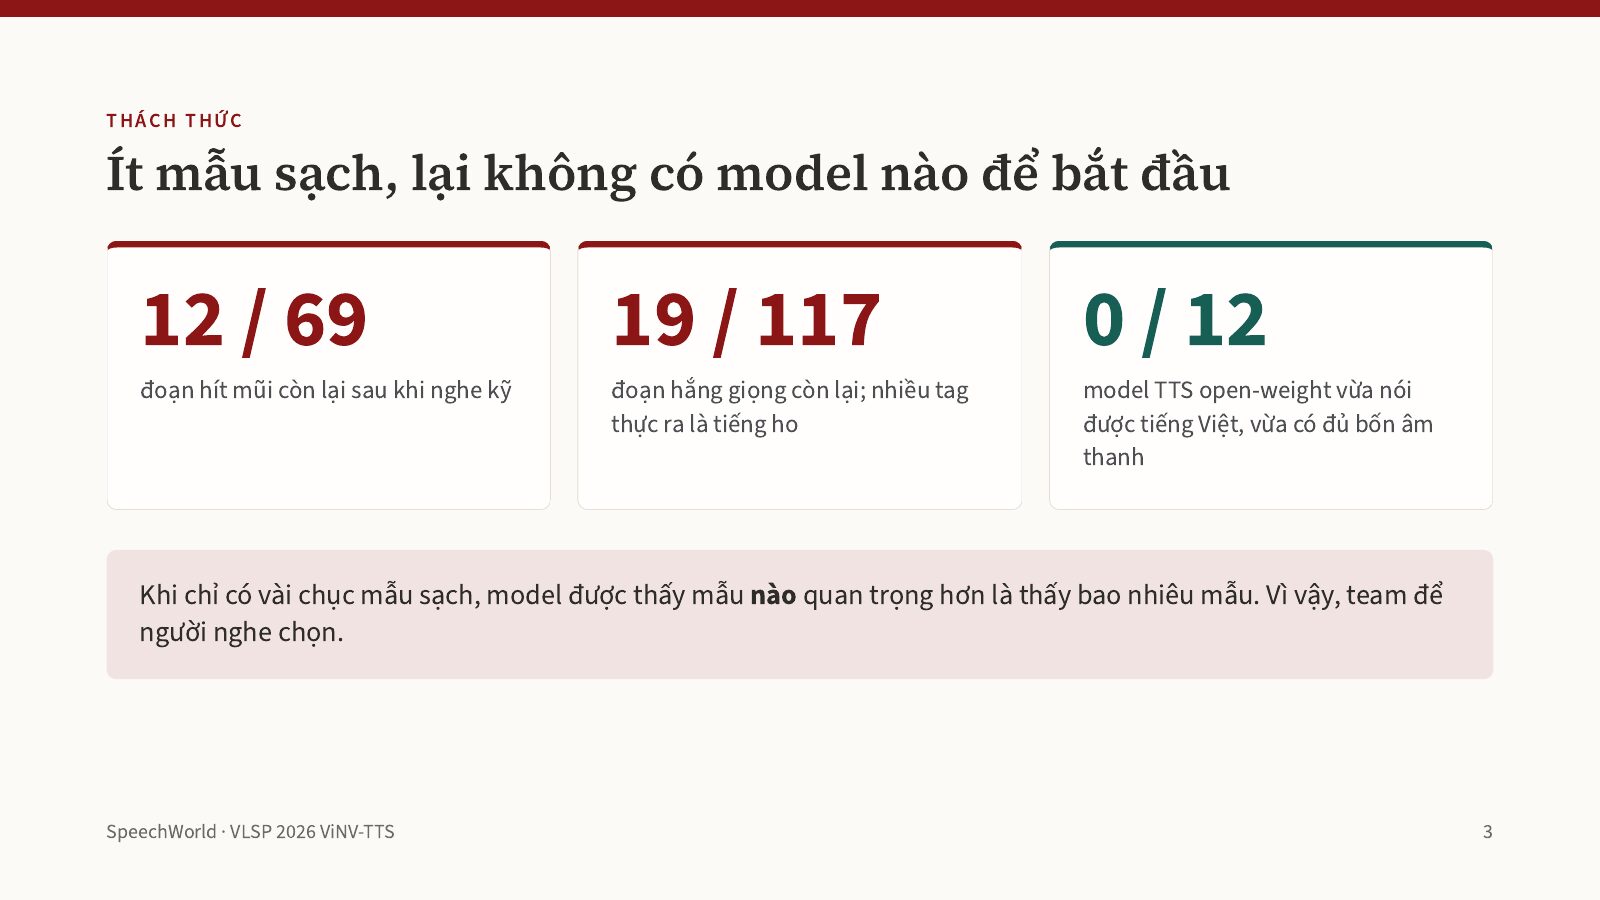
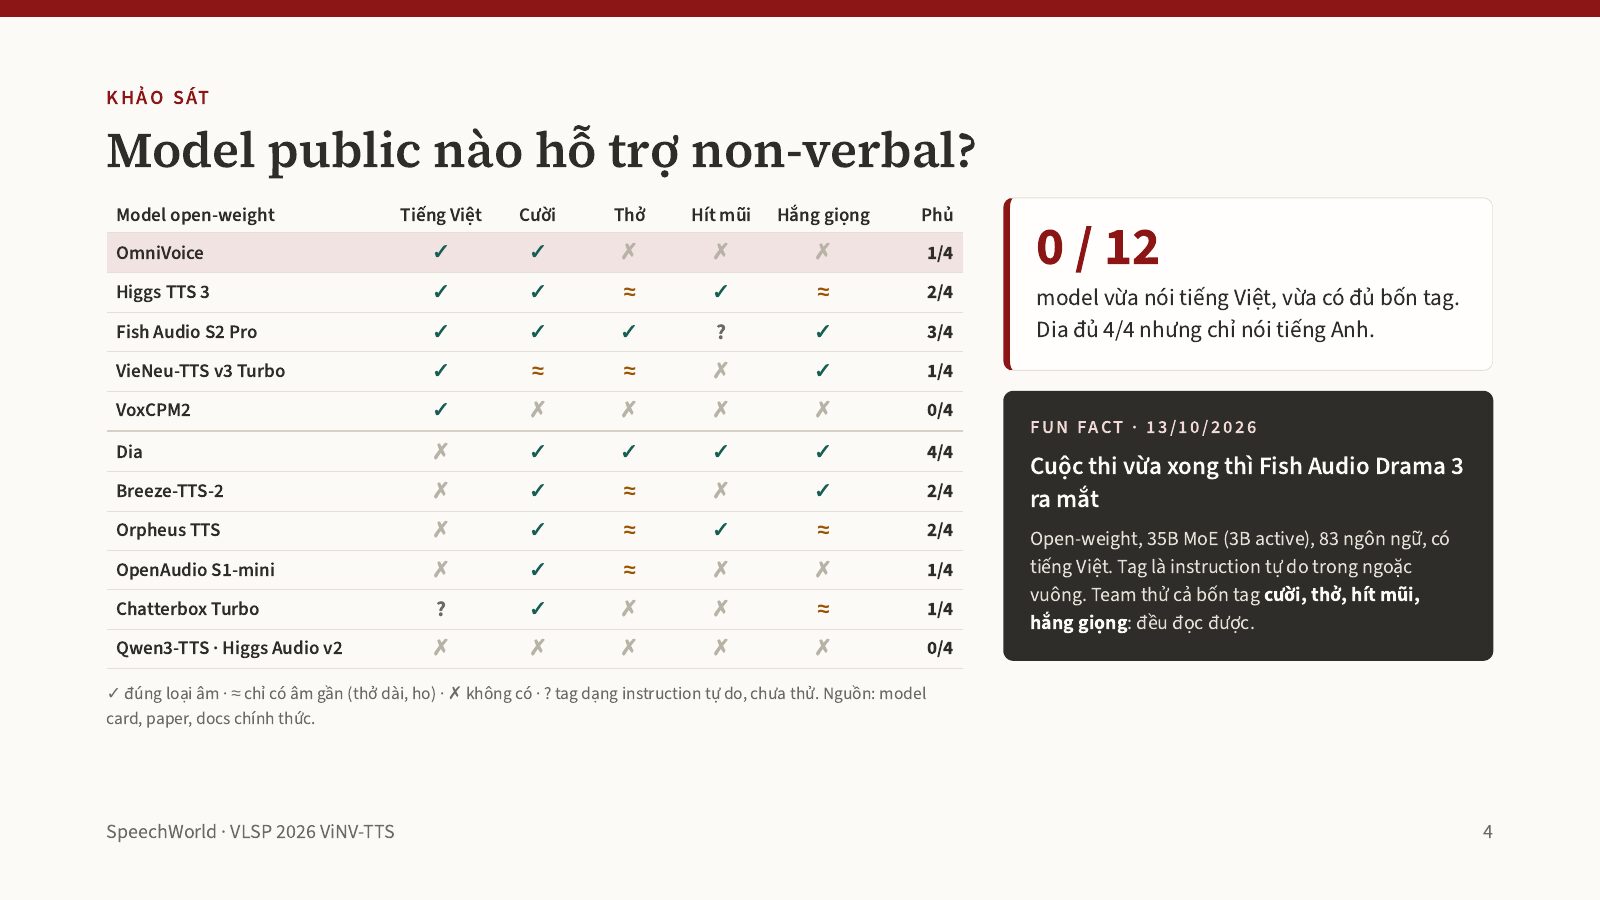
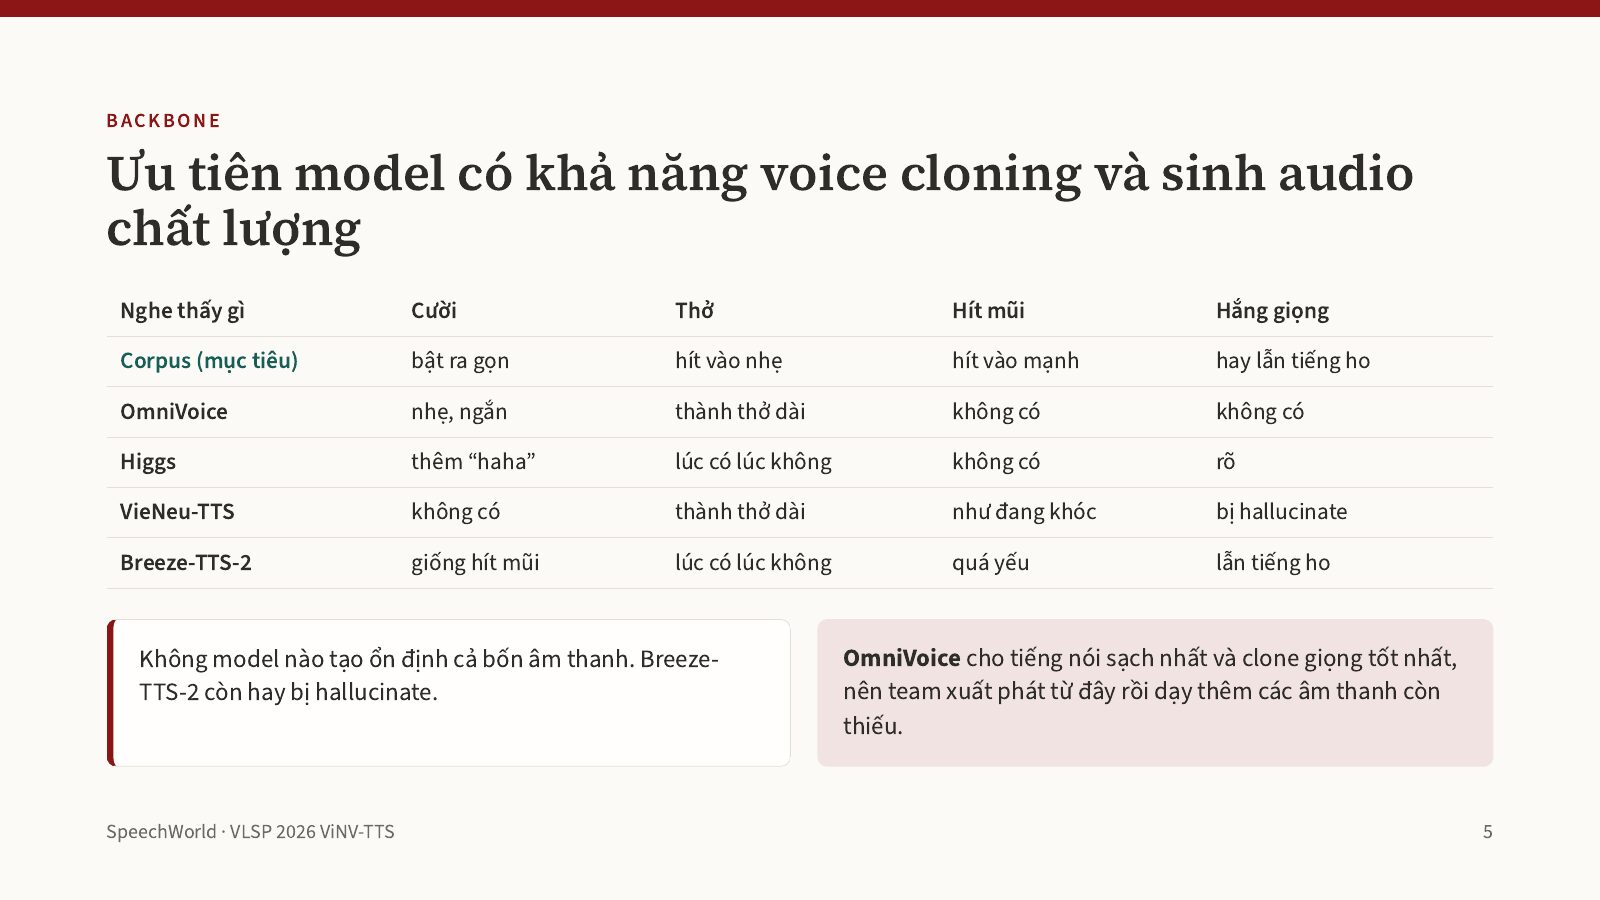
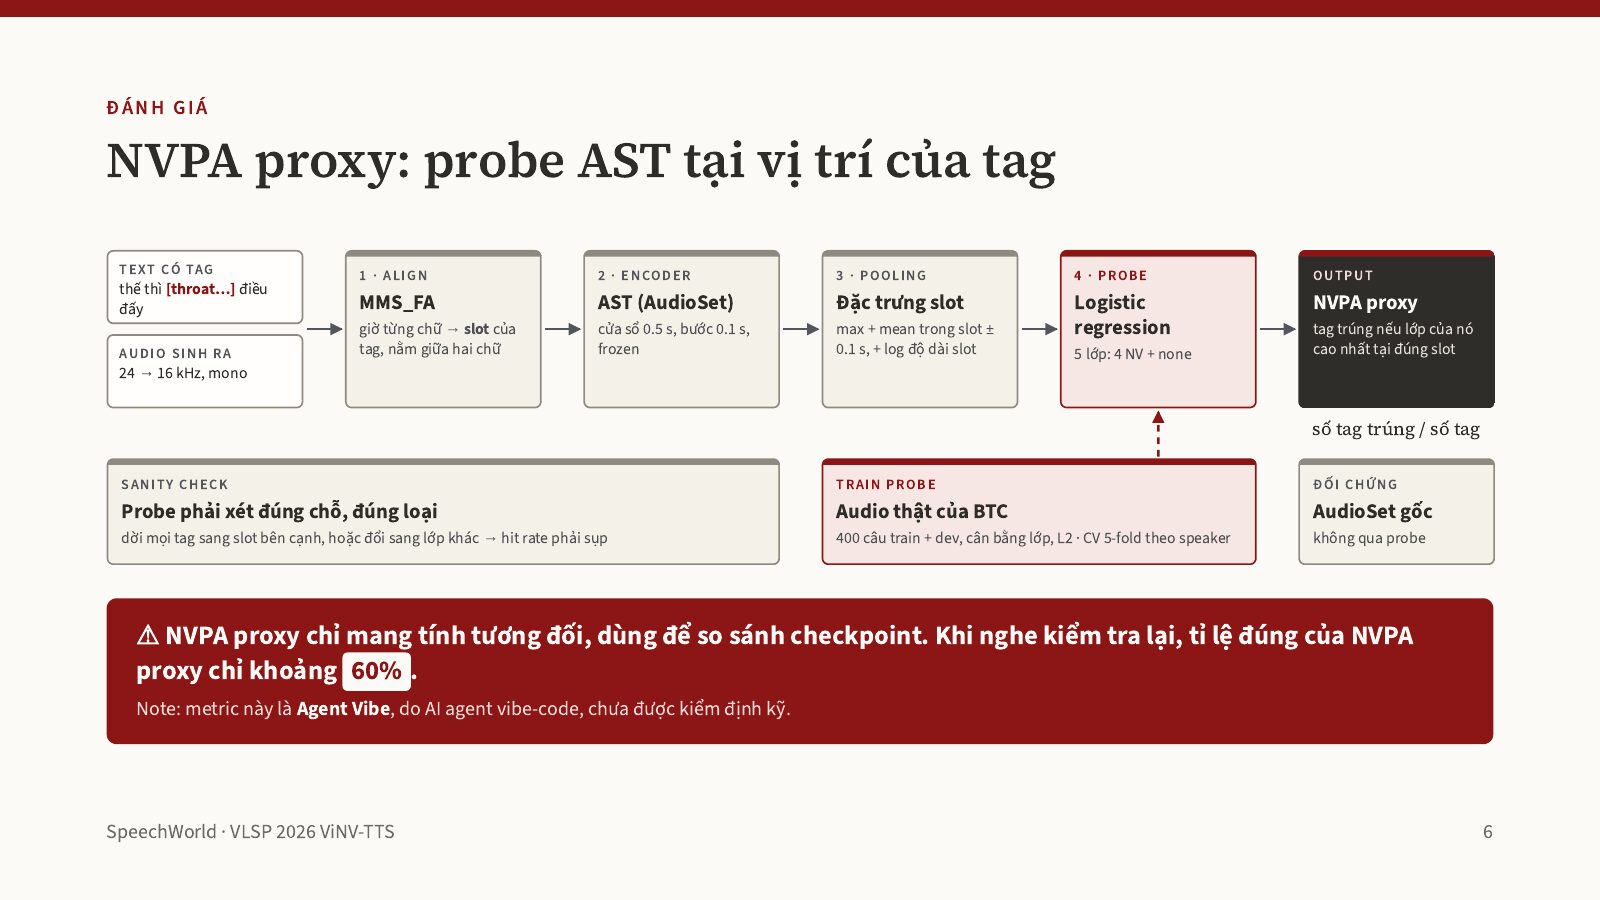
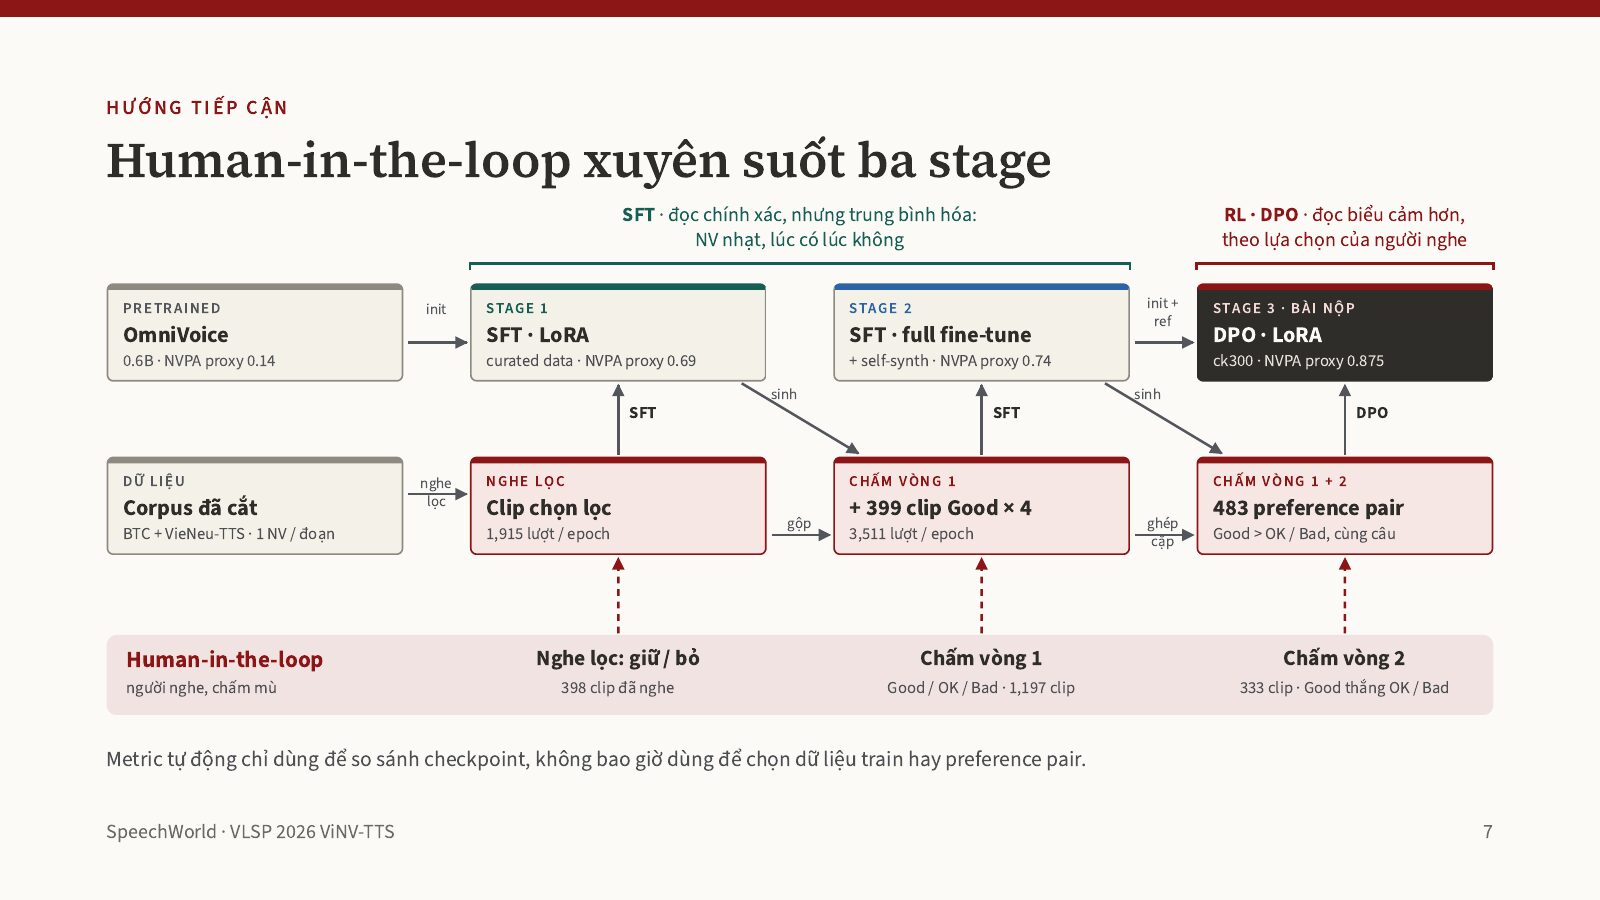
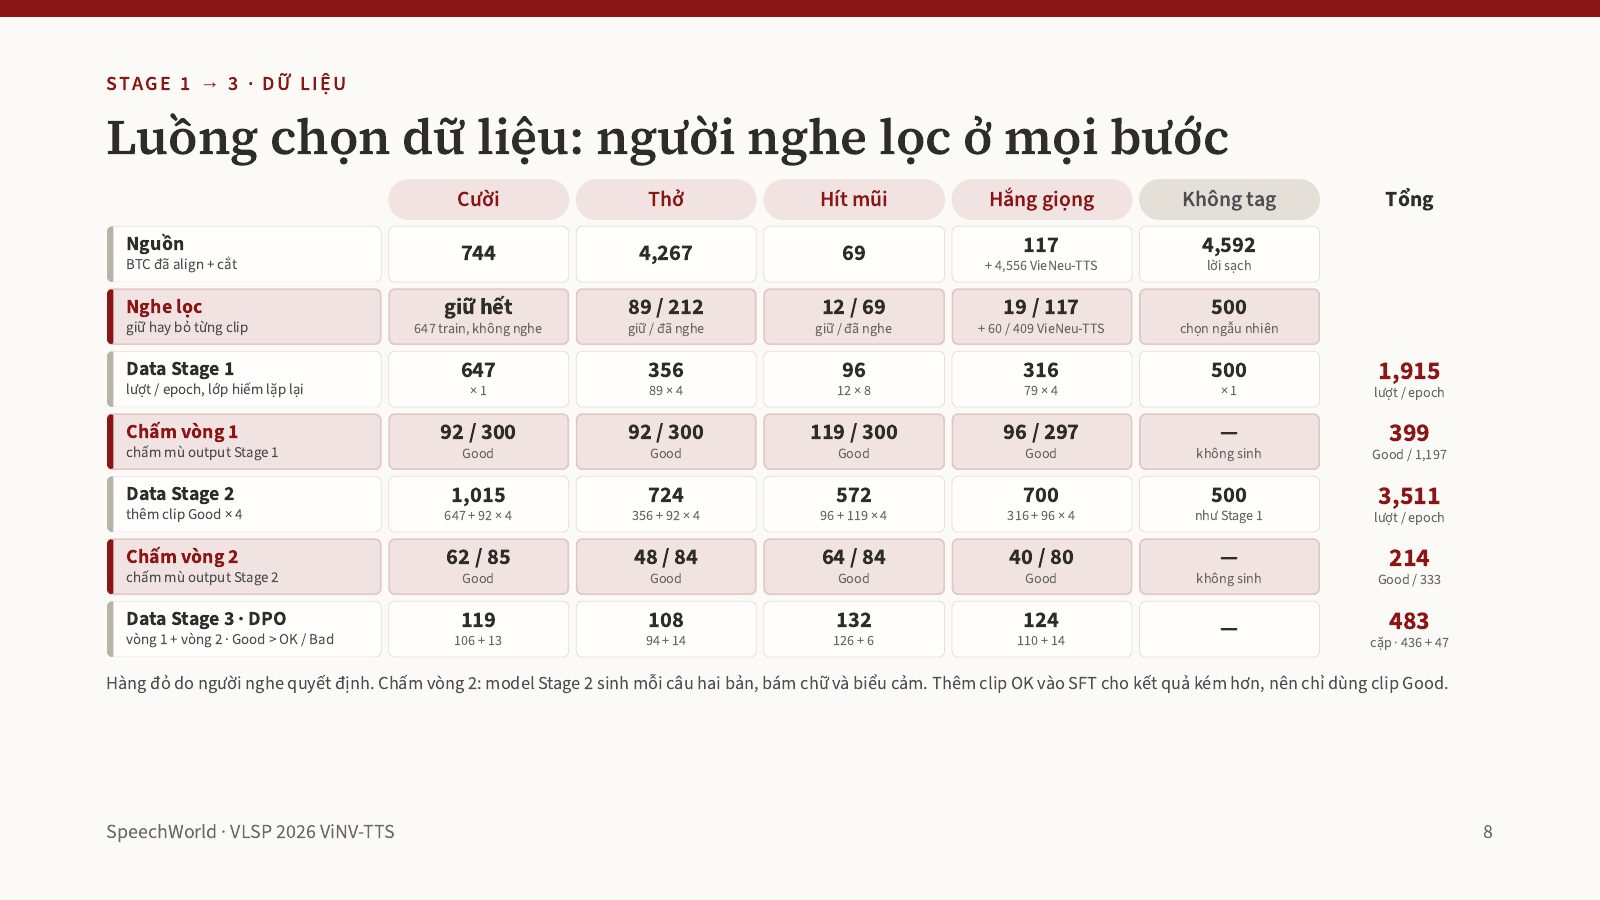
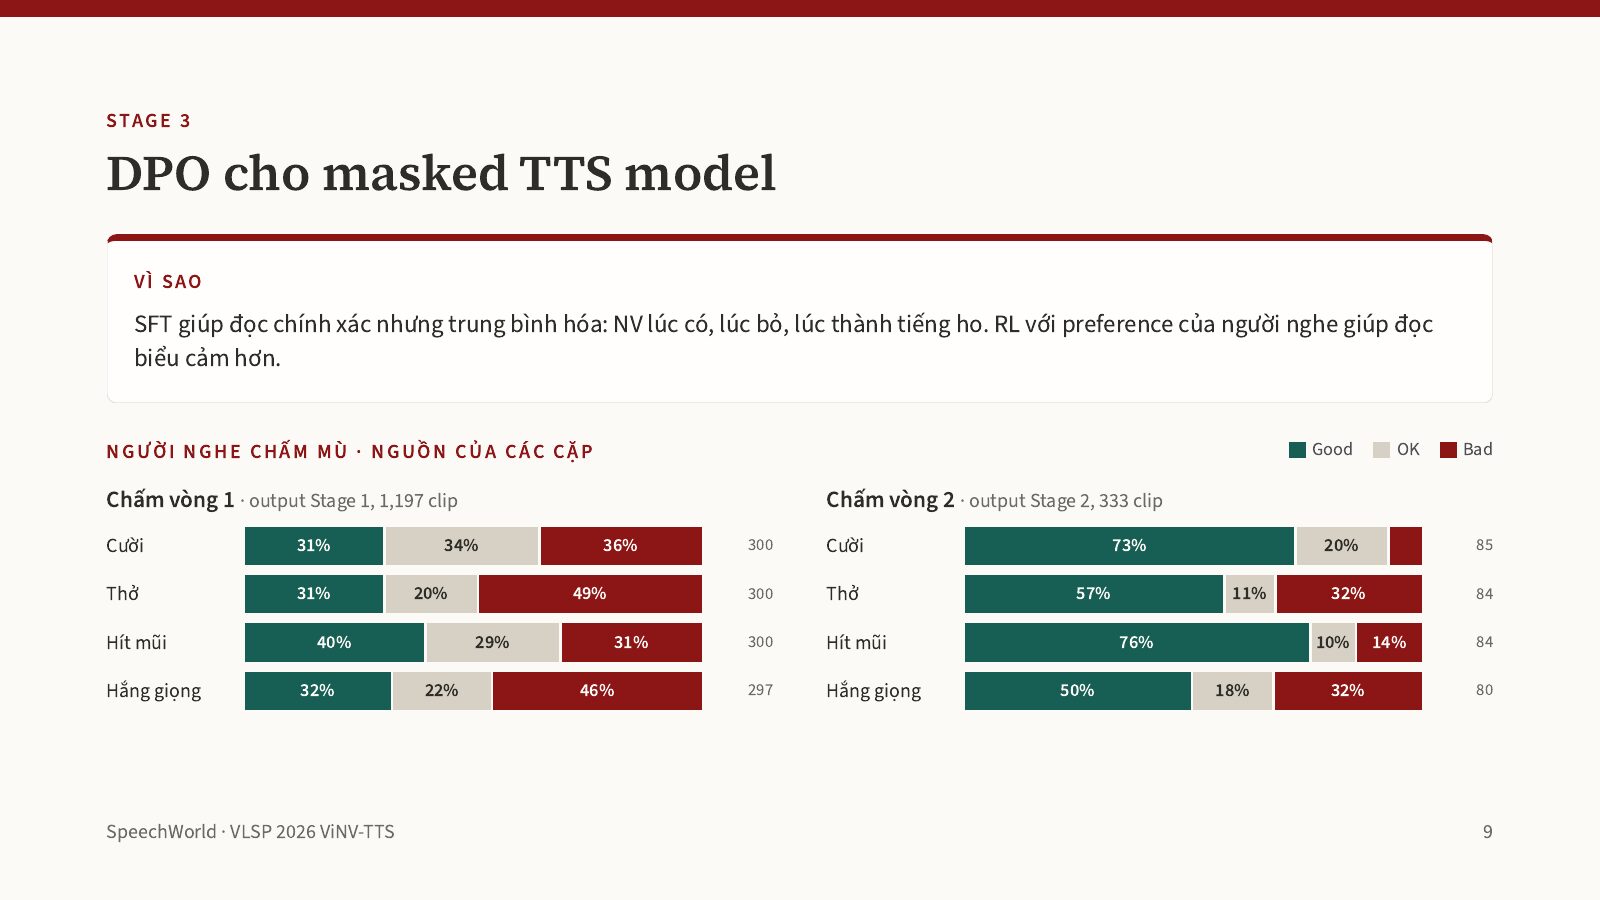
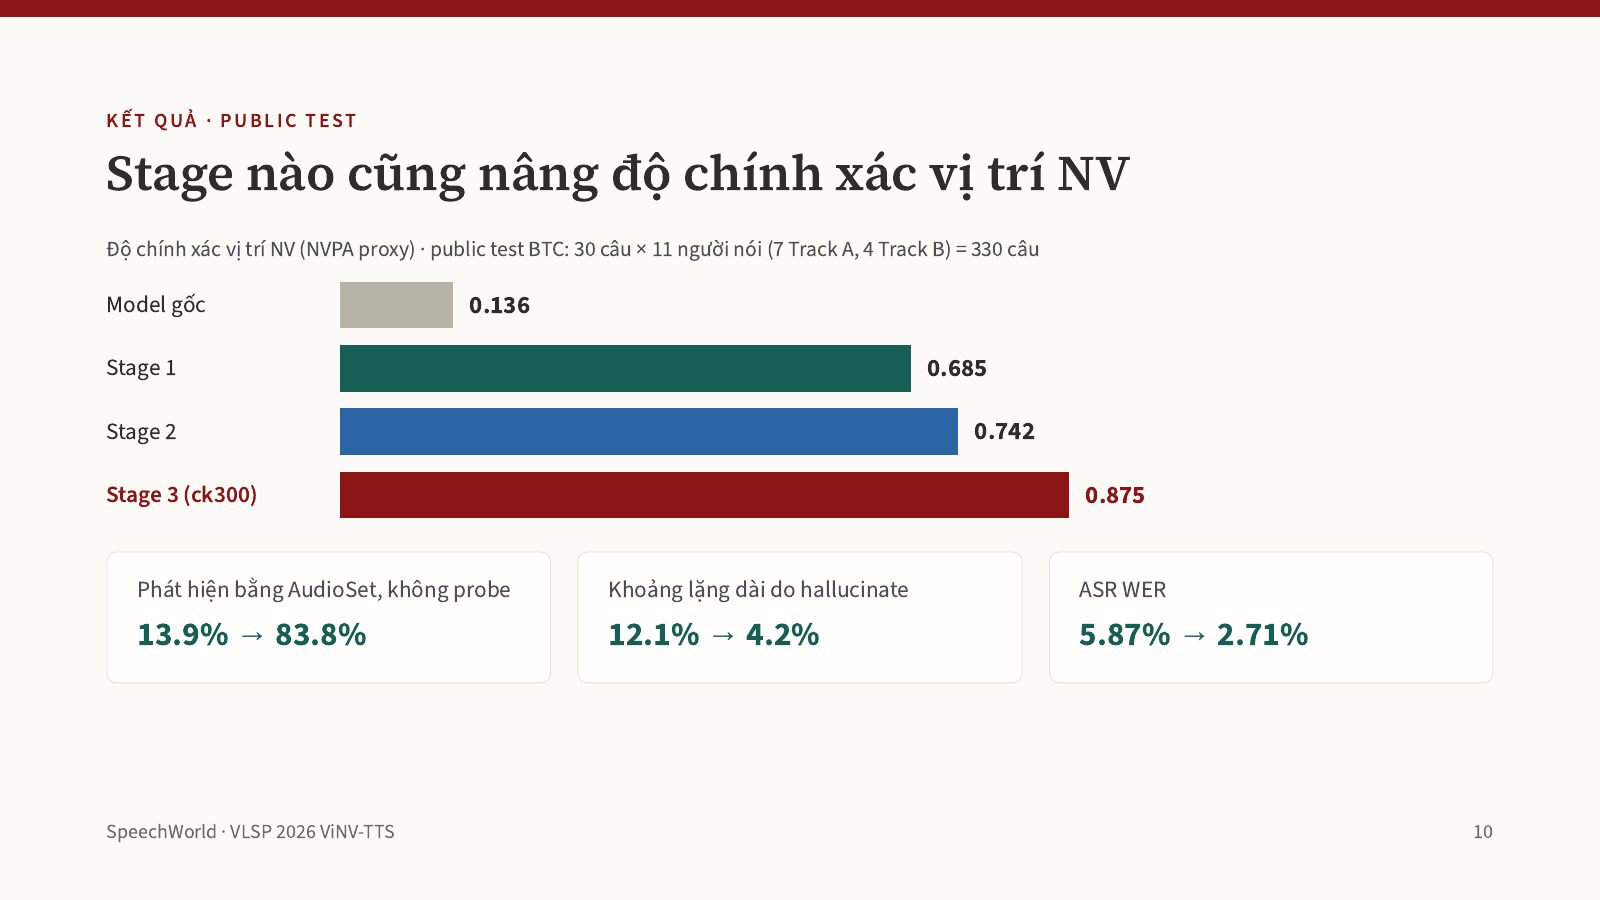
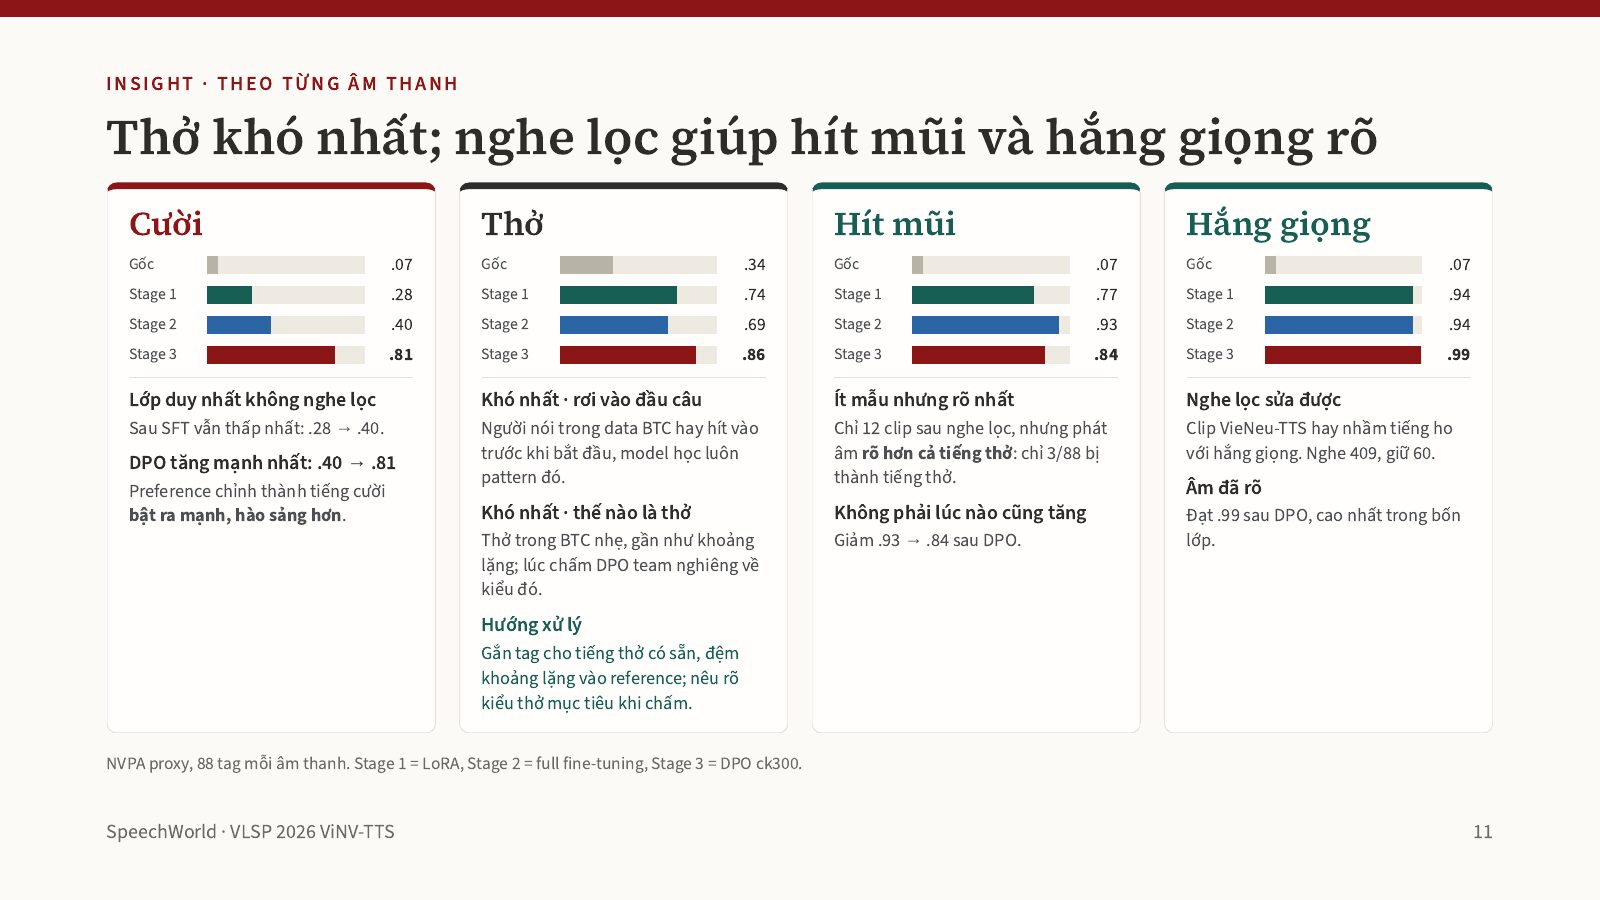
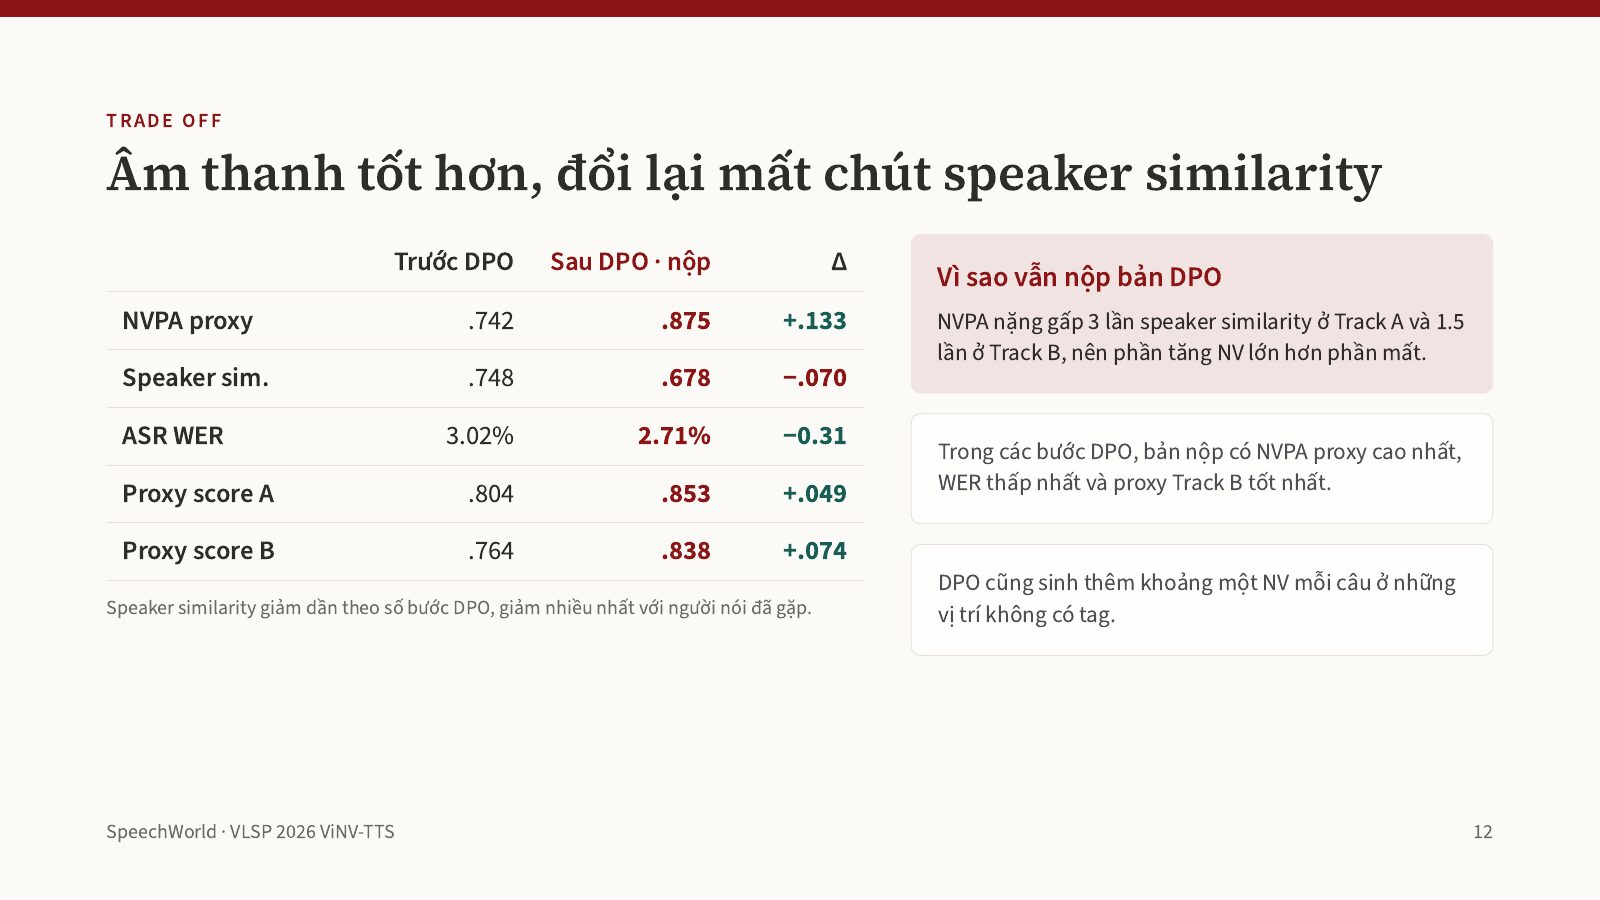
Few open text-to-speech (TTS) models can render non-verbal vocalizations (NVs) such as laughter, breathing, sniffing and throat clearing, and fewer still support Vietnamese. We describe our system for the VLSP 2026 ViNV-TTS shared task, which requires each tagged NV to be rendered at its intended position while the voice of the target speaker is preserved. Starting from a multilingual masked generative TTS model, we build a human-in-the-loop pipeline in which listener judgments decide all training signal. Human listening turns a small, noisily tagged corpus into clean single-NV examples, selects the best of the model’s own synthesized speech as additional training data, and supplies preference pairs for Direct Preference Optimization, which we adapt to masked token prediction by estimating sequence likelihoods from masked-token log-probabilities. The pipeline teaches the model all four NV classes from a few dozen clean examples of the rarest ones, and on the public test, preference optimization yields the largest improvement in NV placement at a small cost in speaker similarity.
Slides
Interactive Experiment Map
The full experiment notebook (in Vietnamese): data flow per tag, listening rounds, per-checkpoint results, model architecture and the NVPA probe, with playable samples. Open full screen ↗
Audio Samples
Generated by the submitted system from self-written sentences, using two preset voices of VieNeu-TTS as references (no organizer audio or text). Each clip is the best of 4 seeds, so these are selected rather than random samples.
Reference voice · MaleVieNeu-TTS preset 05
Reference voice · FemaleVieNeu-TTS preset 04
Hôm qua tôi đi chợ quên mang ví, đứng trả tiền mới biết [laughter] ngại không để đâu cho hết.
[laughter] Thôi chị ơi, em nói thật mà, con mèo nhà em nó tự mở được tủ lạnh luôn.
Thằng bé nhà tôi bảo lớn lên muốn làm siêu nhân để khỏi phải đi học [laughter]
Lúc đầu em cứ tưởng anh ấy nói đùa [laughter] ai ngờ anh ấy làm thật.
Leo hết chín tầng cầu thang mới tới nơi [breathing] thang máy lại đang sửa.
[breathing] Được rồi, mình bắt đầu lại từ đầu nhé, lần này chậm hơn một chút.
Tôi vừa chạy bộ quanh hồ ba vòng xong, giờ mệt quá [breathing]
Chuyện này em nghĩ mãi rồi [breathing] em vẫn muốn thử thêm một lần nữa.
Trời trở lạnh nên tôi bị sổ mũi mấy hôm nay [sniff] uống thuốc mãi chưa khỏi.
[sniff] Xin lỗi, xem phim đến đoạn cuối em không cầm được nước mắt.
Mùi phở ở đầu ngõ thơm quá, sáng nào đi qua tôi cũng phải dừng lại [sniff]
Mẹ gọi điện hỏi bao giờ về quê [sniff] em chỉ biết nói là sắp rồi.
[throatclearing] Xin chào các bạn, hôm nay chúng ta sẽ nói về kế hoạch của quý tới.
Theo số liệu mới nhất [throatclearing] doanh thu tháng này tăng khoảng mười phần trăm.
Tôi xin phép phát biểu thêm một ý nhỏ [throatclearing] trước khi kết thúc cuộc họp.
Cảm ơn mọi người đã lắng nghe, có câu hỏi gì thì cứ hỏi nhé [throatclearing]
Paper
Competition Award Certificates
VLSP Competition Award – First Rank, presented at the 12th Workshop on Vietnamese Language and Speech Processing (VLSP 2026), Ho Chi Minh City, Vietnam, November 15, 2026.
At the VLSP 2026 Workshop